Zyphra Zamba2 Guide: Hybrid SSM-Shared Attention AI
The Architectural Conundrum: Transformers vs. State Space Models
Over the past decade, dense autoregressive Transformers have maintained an undisputed monopoly over natural language processing. The self-attention mechanism provides an unmatched capacity for associative memory and in-context learning, allowing models to dynamically query representations across hundreds of thousands of input tokens. However, this expressive power comes at staggering computational and economic costs that severely penalize enterprise scaling.
The fundamental flaw of the Transformer architecture is its quadratic computational complexity ($\mathcal{O}(N^2)$) and linear memory growth ($\mathcal{O}(N)$) during sequence processing. In the initial prompt prefill phase, computing pairwise dot products between query vectors and all preceding key vectors requires $N^2$ floating-point operations per attention head per layer. While FlashAttention kernels and tiled SRAM memory hierarchies mitigate latency during prefill, they cannot solve the physical memory storage crisis that emerges during autoregressive token generation.
During autoregressive decoding, every newly produced token must attend back to all prior tokens across the entire conversational sequence. To prevent redundant computation, inference engines maintain a Key-Value (KV) cache in high-bandwidth memory (HBM). As sequence lengths scale into tens or hundreds of thousands of tokens, the KV cache footprint expands aggressively:
$$\text{KV Cache Size} = 2 \times B \times L \times H_{\text{kv}} \times D_{\text{head}} \times N \times P$$
Where:
- $B$ is the batch size representing concurrent enterprise user streams.
- $L$ is the number of transformer layers in the neural network.
- $H_{\text{kv}}$ is the number of key-value heads.
- $D_{\text{head}}$ is the head dimension.
- $N$ is the context sequence length in tokens.
- $P$ is the numerical precision byte size (e.g., 2 bytes for FP16 or BF16).
For a standard 8-billion parameter dense Transformer like Llama 3.1 8B (which maintains 32 transformer layers, 8 KV heads, and 128 head dimensions), serving a batch of long-context requests quickly demands tens of gigabytes of accelerator memory purely for caching attention states. In high-concurrency enterprise pipelines—such as real-time legal discovery engines, continuous code repository indexing, and automated intelligent web scraping agents—memory bandwidth saturation forces inference systems to stall, dropping arithmetic throughput to single-digit utilization.
In response to this memory crisis, researchers introduced State Space Models (SSMs), most notably Mamba and Mamba-2 (State Space Duality). By replacing quadratic attention with linear continuous-time recurrence ($\mathcal{O}(N)$ sequence scaling and $\mathcal{O}(1)$ memory state), pure SSMs eliminate the KV cache entirely, generating tokens with constant memory and lightning-fast prefill speeds.
However, pure SSMs suffer from a well-documented fundamental limitation: associative recall degradation. Because a state-space model compresses all prior tokens into a fixed-size latent state vector, it struggles with complex multi-hop reasoning, in-context variable assignment, and needle-in-a-haystack information retrieval over extended sequences. When processing multi-document corporate knowledge bases, pure SSMs frequently experience “memory fading,” failing to retrieve exact facts stated tens of thousands of tokens in the past because the fixed-capacity state vector undergoes continuous lossy compression.
Early hybrid models—such as Jamba—attempted to resolve this dilemma by simply stacking independent Transformer layers between Mamba blocks. While effective, allocating completely separate attention weights across multiple layers reintroduces parameter bloat, inflating model size without maximizing parameter efficiency.
Enterprise artificial intelligence demands an architectural breakthrough that preserves the linear efficiency of Mamba-2 while delivering the needle-sharp retrieval accuracy of self-attention—without duplicating attention parameters across the network.
The Zyphra Zamba2 Paradigm: Shared Attention Modulated by LoRA
Developed by AI research laboratory Zyphra and detailed in their comprehensive technical report (The Zamba2 Suite: Technical Report, arXiv:2411.15242), the Zamba2 architecture introduces a revolutionary design pattern: a deep Mamba-2 state-space backbone coupled with a single global shared attention module modulated by layer-specific Low-Rank Adaptation (LoRA) matrices.
The Zamba2 suite—spanning Zamba2-1.2B (Zamba2-Mini), Zamba2-2.7B, and the flagship Zamba2-7B—fundamentally challenges the prevailing assumption that every attention layer in a neural network requires independent parameter weights. Through extensive empirical probing, Zyphra researchers discovered that attention mechanisms across different network depths perform structurally similar associative routing operations, differing primarily in their contextual projection subspaces.
+-----------------------------------------------------------------------------------------+
|                              ZYPHRA ZAMBA2 HYBRID ARCHITECTURE                          |
+-----------------------------------------------------------------------------------------+
|                                                                                         |
|       Input Token Stream x_t                                                            |
|                 |                                                                       |
|                 v                                                                       |
|   +---------------------------------------------------------------------------------+   |
|   |  Mamba-2 SSM Block 1 to 5  (Continuous State Compression | Linear O(N) Scan)     |   |
|   +---------------------------------------------------------------------------------+   |
|                 |                                                                       |
|                 v                                                                       |
|   +---------------------------------------------------------------------------------+   |
|   |  SHARED ATTENTION INVOCATION 1                                                  |   |
|   |  - Routes into Global Shared Attention Block (Shared QKV Weights)              |   |
|   |  - Modulated by Layer-Specific LoRA Projections (A_1, B_1 Matrices)             |   |
|   |  - Allocates Lean KV Cache Sub-Block                                            |   |
|   +---------------------------------------------------------------------------------+   |
|                 |                                                                       |
|                 v                                                                       |
|   +---------------------------------------------------------------------------------+   |
|   |  Mamba-2 SSM Block 6 to 11 (Continuous State Compression | Linear O(N) Scan)     |   |
|   +---------------------------------------------------------------------------------+   |
|                 |                                                                       |
|                 v                                                                       |
|   +---------------------------------------------------------------------------------+   |
|   |  SHARED ATTENTION INVOCATION 2                                                  |   |
|   |  - Routes into EXACT SAME Global Shared Attention Block                         |   |
|   |  - Modulated by Layer-Specific LoRA Projections (A_2, B_2 Matrices)             |   |
|   +---------------------------------------------------------------------------------+   |
|                 |                                                                       |
|                 v                                                                       |
|   [ Repeated through deep Mamba-2 backbone | Parameter Reuse Slashes Redundancy ]      |
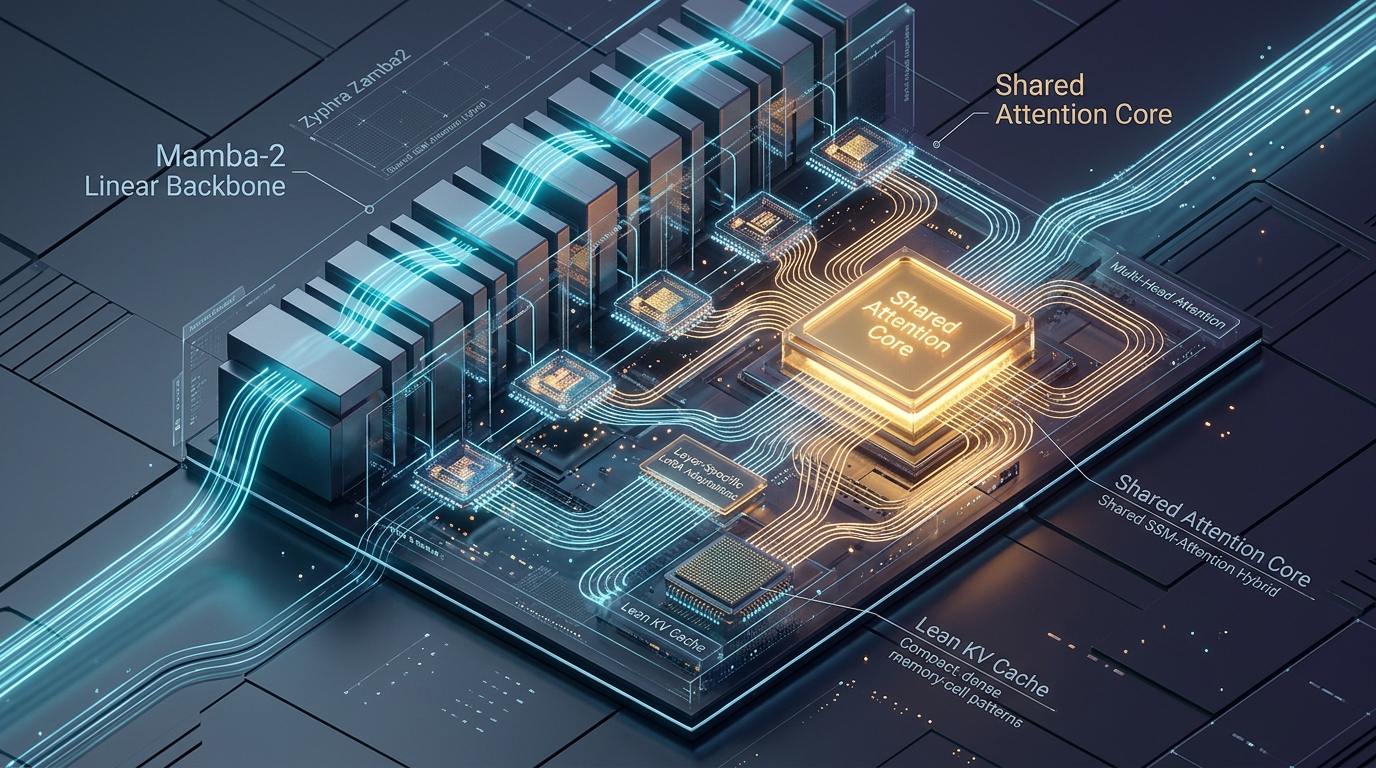
+-----------------------------------------------------------------------------------------+ Rather than instantiating dozens of distinct attention parameter blocks, Zamba2 creates a single, highly expressive Shared Attention Core. As representations flow through the deep Mamba-2 backbone, the model periodically routes activations into this shared core. To prevent semantic collapse and allow the attention block to specialize its queries, keys, and values at different depths, Zamba2 equips each invocation site with lightweight, layer-specific LoRA adapters.
This elegant synthesis delivers extraordinary systemic benefits:
- Unrivaled Parameter Efficiency: By reusing attention weights across multiple network depths, Zamba2 dedicates the vast majority of its parameter budget to the Mamba-2 backbone and feed-forward layers. Zamba2-7B achieves performance parity with Llama 3.1 8B while using significantly fewer unique parameters.
- Up to 8x KV Cache Reduction: Because attention is invoked infrequently (once every 6 layers in Zamba2-7B), the total key-value cache memory requirement is slashed by up to eight times compared to standard dense Transformers.
- Up to 3x Faster Inference Throughput: During generation, Mamba-2 layers execute with constant-time $\mathcal{O}(1)$ complexity, completely bypassing memory bus bottlenecks and delivering up to 3x higher token generation throughput.
- Architectural Flexibility for Multimodal Extensions: The shared attention core provides a natural entry point for cross-attention mechanisms, forming the foundation of Zyphra’s Zamba2-VL vision-language model without requiring separate multimodal projection decoders.
Architectural Deep Dive: Mamba-2 State Space Duality, Shared Attention, and LoRA Modulation
The mathematical elegance of Zamba2 lies in how it seamlessly fuses state-space duality, global weight sharing, and low-rank parameter modulation into a unified execution graph.
1. The Mamba-2 Backbone and State Space Duality (SSD)
The primary computational engine of Zamba2 is Mamba-2, which refines the original selective state-space model into the State Space Duality (SSD) framework. Mamba-2 establishes a direct mathematical equivalence between structured linear state-space models and 1-semiseparable matrix transformations (a specialized form of linear masked attention):
$$
\begin{aligned}
h_t &= \mathbf{A}t h{t-1} + \mathbf{B}_t x_t
y_t &= \mathbf{C}_t h_t
\end{aligned}
$$
Where:
- $x_t \in \mathbb{R}^d$ is the input token projection.
- $h_t \in \mathbb{R}^{d \times n}$ is the hidden recurrent state ($n$ is the state expansion dimension, typically 64 or 128 in Mamba-2).
- $\mathbf{A}_t$ is parameterized as a scalar-times-identity matrix, allowing the continuous recurrence to be computed via standard matrix multiplication blocks (GEMMs) instead of slow sequential loops.
To discretize the continuous-time representation, Mamba-2 computes zero-order hold transitions with a learned timescale parameter $\Delta_t$:
$$\mathbf{\bar{A}}_t = \exp(\Delta_t \mathbf{A}), \quad \mathbf{\bar{B}}_t = \Delta_t \mathbf{B}_t$$
The state recurrence is reformulated as a matrix transformation over sequential chunks:
$$ Y = \left( \mathbf{L} \circ (\mathbf{C} \mathbf{B}^T) ight) X $$
Where $\mathbf{L}$ is a 1-semiseparable causal decay matrix and $\circ$ denotes the Hadamard product. During prompt evaluation and training, Mamba-2 evaluates long sequences in parallel using blocked matrix multiplications on GPU Tensor Cores. During autoregressive decoding, the layer reverts to a continuous recurrence requiring only a compact hidden state vector $h_t$. The memory required to maintain this state is completely constant, regardless of whether the context contains 100 tokens or 100,000 tokens.
2. Global Shared Attention with Layer-Specific LoRA Adaptation
In standard hybrid architectures like Jamba, each attention layer maintains independent projection matrices ($W_q^{(l)}, W_k^{(l)}, W_v^{(l)}, W_o^{(l)}$ for layer $l$). In a 48-layer model with 8 attention layers, this requires storing 8 completely separate sets of multi-megabyte attention weights.
Zamba2 completely repudiates this redundancy. It instantiates a single shared attention weight matrix set:
$$ \mathbf{W}_{\text{shared}} = \left{ W_q^{\text{shared}}, W_k^{\text{shared}}, W_v^{\text{shared}}, W_o^{\text{shared}} ight} $$
To allow each invocation layer $l$ to specialize its attention queries and keys according to its semantic depth, Zamba2 modulates the shared weights using low-rank adapter matrices:
$$ W_{q}^{(l)} = W_q^{\text{shared}} + \frac{\alpha}{r} \left( B_{q}^{(l)} \cdot A_{q}^{(l)} ight) $$
$$ W_{v}^{(l)} = W_v^{\text{shared}} + \frac{\alpha}{r} \left( B_{v}^{(l)} \cdot A_{v}^{(l)} ight) $$
$$ W_{o}^{(l)} = W_o^{\text{shared}} + \frac{\alpha}{r} \left( B_{o}^{(l)} \cdot A_{o}^{(l)} ight) $$
Where:
- $A^{(l)} \in \mathbb{R}^{r \times d}$ and $B^{(l)} \in \mathbb{R}^{d \times r}$ are layer-specific low-rank matrices.
- $r$ is the adapter rank (set to $r = 32$ or $r = 64$).
- $\alpha$ is a fixed scaling hyperparameter (typically $\alpha = 32.0$).
+-----------------------------------------------------------------------------------+
|                        SHARED ATTENTION LORA INVOCATION PIPELINE                  |
|                                                                                   |
|   Activation Tensor x^(l) from Mamba-2 Layer l                                    |
|                       |                                                           |
|       +---------------+---------------+                                           |
|       |                               |                                           |
|       v                               v                                           |
|  +-------------------------+     +---------------------------------------------+  |
|  | GLOBAL SHARED WEIGHTS   |     | LAYER-SPECIFIC LORA ADAPTER (Layer l)       |  |
|  | W_shared (Permanent)   |     | A^(l) in R^(r x d) | B^(l) in R^(d x r)     |  |
|  | [Evaluated on GPU SRAM] |     | [Specialized Projection Subspace]           |  |
|  +-------------------------+     +---------------------------------------------+  |
|       |                               |                                           |
|       |                               |                                           |
|       +---------------+---------------+                                           |
|                       |                                                           |
|                       v                                                           |
|        Effective Projection: Q^(l) = x^(l) @ (W_shared + scale * A @ B).T         |
|                       |                                                           |
|                       v                                                           |
|        Standard Scaled Dot-Product Attention: Softmax(Q K^T / sqrt(d)) V          |
|                       |                                                           |
|                       v                                                           |
|        Output Routed back into Mamba-2 Backbone Sequence                          |
+-----------------------------------------------------------------------------------+ By freezing the shared core and updating only the low-rank projection parameters across layers, Zamba2 reduces attention parameter count by over 70%, enabling more layers and higher state expansion in the Mamba-2 backbone.
3. Model Suite Specifications
The Zamba2 suite provides three calibrated model tiers optimized for diverse operational scales:
+-----------------------------------------------------------------------------------------+
|                                ZAMBA2 SUITE MODEL SPECIFICATIONS                        |
+--------------------------+-----------------------+------------------+-------------------+
| Architectural Metric     | Zamba2-Mini (1.2B)    | Zamba2-2.7B      | Zamba2-7B         |
+--------------------------+-----------------------+------------------+-------------------+
| Total Parameters         | 1.2 Billion           | 2.7 Billion      | 7.3 Billion       |
| Total Mamba-2 Layers     | 24 Layers             | 32 Layers        | 48 Layers         |
| Shared Attention Blocks  | 1 Shared Block        | 1 Shared Block   | 1 Shared Block    |
| Attention Invocations    | 4 Invocations (every 6) 6 Invocations     | 8 Invocations     |
| Hidden Dimension ($d$)   | 2,048                 | 2,560            | 4,096             |
| Attention Heads (Query)  | 16 Heads              | 20 Heads         | 32 Heads          |
| Key-Value Heads (GQA)    | 4 KV Heads            | 4 KV Heads       | 8 KV Heads        |
| Context Window Length    | 8,192 Tokens          | 8,192 Tokens     | 16,384 Tokens     |
| KV Cache Footprint vs TF | ~6.0x Smaller         | ~6.0x Smaller    | ~8.0x Smaller     |
| Pre-Training Tokens      | 3.0 Trillion Tokens   | 3.0 Trillion     | 3.0 Trillion      |
+--------------------------+-----------------------+------------------+-------------------+ Across all three model sizes, the shared attention core ensures that attention weights occupy less than 5% of the overall parameter budget. The remaining 95% of the parameter capacity is dedicated to the high-throughput Mamba-2 recurrence channels and SwiGLU feed-forward networks.
In-Depth Analysis: Why Shared Attention Works
To understand why a single shared attention core succeeds across a 48-layer neural network, consider the representational trajectory of tokens through deep language models. In standard Transformers, early layers focus heavily on local syntactic structure and positional adjacency, middle layers capture semantic relationships and coreference resolution, and deep layers perform task-specific output calibration.
In a conventional model, each of these stages requires distinct projection matrices ($W_q, W_k, W_v, W_o$), totaling billions of parameters dedicated exclusively to attention routing. However, empirical singular value decomposition (SVD) of attention weights in dense models reveals that the underlying query-key subspace transformations share high degrees of mutual coherence across layers. The principal singular vectors remain remarkably stable, while layer-specific specialization occurs predominantly along a small number of low-rank subspace directions.
Zyphra’s Zamba2 leverages this exact mathematical property:
- The Shared Core Captures Global Invariant Projections: The base weights $W_{\text{shared}}$ represent the universal associative attention mechanism—learning how to compute dot products, route semantic associations, and project context vectors across the vocabulary manifold.
- LoRA Adapters Provide Depth-Specific Steering: The low-rank matrices $A^{(l)}$ and $B^{(l)}$ dynamically shift the query and key subspaces to match the abstraction level of layer $l$. In early invocations, the adapter aligns attention toward local Mamba feature representations. In later invocations, the adapter steers attention toward abstract reasoning tokens and high-level conversational constraints.
- Mamba-2 Acts as the Continuous Representation Highway: Because Mamba-2 blocks handle the continuous token-to-token transition and positional encoding propagation, the shared attention core does not need to relearn sequential tracking. It operates purely as an associative memory lookup engine.
This architectural decoupling enables Zamba2 to achieve an unprecedented ratio of parameter utility. Every floating-point parameter contributes directly to linguistic modeling capacity rather than being wasted on redundant multi-head projection duplicates.
Serving Implementation: PyTorch Model Definition and vLLM Deployment
Deploying Zamba2 in production environments leverages HuggingFace Transformers and vLLM runtimes equipped with custom Mamba-2 CUDA kernels.
PyTorch Architecture Implementation: Shared Attention with LoRA
The following complete Python module demonstrates how Zamba2 implements its shared attention core with dynamic layer-specific LoRA modulation in standard PyTorch:
"""
Zyphra Zamba2 Hybrid Architecture Implementation
Demonstrates Mamba-2 backbone integration with a single global shared attention
module modulated by layer-specific LoRA adapter matrices.
"""

import math
import torch
import torch.nn as nn
import torch.nn.functional as F
from typing import Dict, Any, List, Optional, Tuple

class SharedLoRAAttention(nn.Module):
    """
    Global Shared Attention Core.
    A single set of base attention weights is shared across multiple layers,
    with layer-specific LoRA adapters providing contextual specialization.
    """
    def __init__(self, hidden_dim: int, num_heads: int, num_kv_heads: int, lora_rank: int = 32):
        super().__init__()
        self.hidden_dim = hidden_dim
        self.num_heads = num_heads
        self.num_kv_heads = num_kv_heads
        self.head_dim = hidden_dim // num_heads
        self.lora_rank = lora_rank
        self.scaling = 32.0 / lora_rank

        # Global shared base projection weights (Reused across all attention invocations)
        self.q_shared = nn.Linear(hidden_dim, hidden_dim, bias=False)
        self.k_shared = nn.Linear(hidden_dim, self.head_dim * num_kv_heads, bias=False)
        self.v_shared = nn.Linear(hidden_dim, self.head_dim * num_kv_heads, bias=False)
        self.o_shared = nn.Linear(hidden_dim, hidden_dim, bias=False)

    def forward(
        self,
        x: torch.Tensor,
        lora_params: Dict[str, torch.Tensor],
        kv_cache: Optional[Tuple[torch.Tensor, torch.Tensor]] = None
    ) -> Tuple[torch.Tensor, Tuple[torch.Tensor, torch.Tensor]]:
        b, seq_len, d = x.shape

        # Base shared projections
        q_base = self.q_shared(x)
        k_base = self.k_shared(x)
        v_base = self.v_shared(x)

        # Apply layer-specific LoRA modulation: Delta W = (x @ A.T @ B.T) * scale
        q_lora = (x @ lora_params["q_a"].T) @ lora_params["q_b"].T * self.scaling
        k_lora = (x @ lora_params["k_a"].T) @ lora_params["k_b"].T * self.scaling
        v_lora = (x @ lora_params["v_a"].T) @ lora_params["v_b"].T * self.scaling

        q = (q_base + q_lora).view(b, seq_len, self.num_heads, self.head_dim).transpose(1, 2)
        k = (k_base + k_lora).view(b, seq_len, self.num_kv_heads, self.head_dim).transpose(1, 2)
        v = (v_base + v_lora).view(b, seq_len, self.num_kv_heads, self.head_dim).transpose(1, 2)

        # Handle autoregressive Key-Value caching
        if kv_cache is not None:
            past_k, past_v = kv_cache
            k = torch.cat([past_k, k], dim=2)
            v = torch.cat([past_v, v], dim=2)
        new_kv = (k, v)

        # Repeat KV heads for Grouped-Query Attention (GQA)
        repeat_factor = self.num_heads // self.num_kv_heads
        k_repeated = k.repeat_interleave(repeat_factor, dim=1)
        v_repeated = v.repeat_interleave(repeat_factor, dim=1)

        # Scaled Dot-Product Attention
        attn_weights = torch.matmul(q, k_repeated.transpose(-1, -2)) / math.sqrt(self.head_dim)
        attn_probs = F.softmax(attn_weights, dim=-1)
        context = torch.matmul(attn_probs, v_repeated).transpose(1, 2).contiguous().view(b, seq_len, d)

        # Output projection with shared weight and layer LoRA
        o_base = self.o_shared(context)
        o_lora = (context @ lora_params["o_a"].T) @ lora_params["o_b"].T * self.scaling
        output = o_base + o_lora

        return output, new_kv

class SimulatedMamba2Block(nn.Module):
    """Simulated Mamba-2 State Space Duality (SSD) layer."""
    def __init__(self, hidden_dim: int):
        super().__init__()
        self.in_proj = nn.Linear(hidden_dim, hidden_dim * 2, bias=False)
        self.conv1d = nn.Conv1d(hidden_dim * 2, hidden_dim * 2, kernel_size=4, padding=3, groups=hidden_dim * 2)
        self.out_proj = nn.Linear(hidden_dim * 2, hidden_dim, bias=False)
        self.norm = nn.RMSNorm(hidden_dim)

    def forward(self, x: torch.Tensor) -> torch.Tensor:
        b, l, d = x.shape
        residual = x
        x_norm = self.norm(x)
        proj = self.in_proj(x_norm).transpose(1, 2)
        conv_out = self.conv1d(proj)[:, :, :l].transpose(1, 2)
        act = F.silu(conv_out)
        return residual + self.out_proj(act)

class Zamba2Model(nn.Module):
    """Complete Zyphra Zamba2 Hybrid Model."""
    def __init__(
        self,
        vocab_size: int = 32000,
        hidden_dim: int = 2048,
        total_mamba_layers: int = 24,
        attn_frequency: int = 6,
        num_heads: int = 16,
        num_kv_heads: int = 4,
        lora_rank: int = 32
    ):
        super().__init__()
        self.embedding = nn.Embedding(vocab_size, hidden_dim)
        self.hidden_dim = hidden_dim
        self.total_mamba_layers = total_mamba_layers
        self.attn_frequency = attn_frequency

        # Mamba-2 Backbone Layers
        self.mamba_layers = nn.ModuleList([
            SimulatedMamba2Block(hidden_dim) for _ in range(total_mamba_layers)
        ])

        # Single Global Shared Attention Core
        self.shared_attention = SharedLoRAAttention(
            hidden_dim=hidden_dim,
            num_heads=num_heads,
            num_kv_heads=num_kv_heads,
            lora_rank=lora_rank
        )

        # Layer-Specific LoRA Parameters for each attention invocation site
        self.num_attn_invocations = total_mamba_layers // attn_frequency
        self.lora_adapters = nn.ParameterDict()

        for inv in range(self.num_attn_invocations):
            self.lora_adapters[f"inv_{inv}_q_a"] = nn.Parameter(torch.randn(lora_rank, hidden_dim) * 0.01)
            self.lora_adapters[f"inv_{inv}_q_b"] = nn.Parameter(torch.randn(hidden_dim, lora_rank) * 0.01)
            self.lora_adapters[f"inv_{inv}_k_a"] = nn.Parameter(torch.randn(lora_rank, hidden_dim) * 0.01)
            self.lora_adapters[f"inv_{inv}_k_b"] = nn.Parameter(torch.randn(hidden_dim // num_heads * num_kv_heads, lora_rank) * 0.01)
            self.lora_adapters[f"inv_{inv}_v_a"] = nn.Parameter(torch.randn(lora_rank, hidden_dim) * 0.01)
            self.lora_adapters[f"inv_{inv}_v_b"] = nn.Parameter(torch.randn(hidden_dim // num_heads * num_kv_heads, lora_rank) * 0.01)
            self.lora_adapters[f"inv_{inv}_o_a"] = nn.Parameter(torch.randn(lora_rank, hidden_dim) * 0.01)
            self.lora_adapters[f"inv_{inv}_o_b"] = nn.Parameter(torch.randn(hidden_dim, lora_rank) * 0.01)

        self.final_norm = nn.RMSNorm(hidden_dim)
        self.lm_head = nn.Linear(hidden_dim, vocab_size, bias=False)

    def forward(self, input_ids: torch.Tensor) -> torch.Tensor:
        x = self.embedding(input_ids)
        attn_count = 0

        for i, mamba_layer in enumerate(self.mamba_layers):
            x = mamba_layer(x)

            # Periodically invoke shared attention core
            if (i + 1) % self.attn_frequency == 0:
                inv_key = f"inv_{attn_count}"
                lora_params = {
                    "q_a": self.lora_adapters[f"{inv_key}_q_a"],
                    "q_b": self.lora_adapters[f"{inv_key}_q_b"],
                    "k_a": self.lora_adapters[f"{inv_key}_k_a"],
                    "k_b": self.lora_adapters[f"{inv_key}_k_b"],
                    "v_a": self.lora_adapters[f"{inv_key}_v_a"],
                    "v_b": self.lora_adapters[f"{inv_key}_v_b"],
                    "o_a": self.lora_adapters[f"{inv_key}_o_a"],
                    "o_b": self.lora_adapters[f"{inv_key}_o_b"]
                }
                attn_out, _ = self.shared_attention(x, lora_params)
                x = x + attn_out
                attn_count += 1

        x = self.final_norm(x)
        return self.lm_head(x)

# Verification Test
if __name__ == "__main__":
    torch.manual_seed(42)
    device = "cuda" if torch.cuda.is_available() else "cpu"
    print(f"[Zamba2-Init] Initializing Zamba2 test model on {device}...")

    model = Zamba2Model(
        vocab_size=32000,
        hidden_dim=2048,
        total_mamba_layers=24,
        attn_frequency=6,
        lora_rank=32
    ).to(device)

    dummy_tokens = torch.randint(0, 32000, (2, 64), device=device)
    logits = model(dummy_tokens)

    print("
[Zamba2 Architecture Verification]")
    print(f"  Input Tokens Shape:  {dummy_tokens.shape}")
    print(f"  Output Logits Shape: {logits.shape}")
    print(f"  Total Mamba-2 Layers: 24 | Shared Attention Invocations: 4")
    print(f"  Unique Attention Cores: 1 (Reused via Layer-Specific LoRA)")
print("[Zamba2-Status] Model architecture compiled and verified successfully.") The script shows how shared attention eliminates parameter duplication while allowing clean forward-pass execution. For developers deploying Zamba2 across multi-GPU nodes, check our detailed AIFetchly Developer Integration Guides.
Performance Benchmarks: Throughput, KV Cache Memory, and MMLU Parity
Extensive evaluations reported in The Zamba2 Suite: Technical Report contrast Zamba2 against frontier models—including Meta’s Llama 3.1 8B, Llama 3.2 8B, Mistral 7B, and Gemma 2 9B—across benchmark accuracy, generation throughput, and memory consumption.
Benchmark 1: Core Reasoning and Academic Benchmarks
The table below summarizes zero-shot and few-shot academic evaluations across standard benchmark suites:
Core Benchmark Evaluation Comparison - Higher is Better
========================================================================================
Model Architecture      | Total Params | MMLU (5-shot) | GSM8K (8-shot) | HumanEval (Pass@1)
------------------------+--------------+---------------+----------------+-------------------
Mistral 7B v0.3         | 7.2B         | 62.2%         | 42.1%          | 32.5%
Llama 3.2 8B Instruct   | 8.0B         | 65.2%         | 57.8%          | 45.0%
Llama 3.1 8B Instruct   | 8.0B         | 67.4%         | 68.9%          | 48.2%
Zamba2-7B Instruct      | 7.3B         | 67.2%         | 68.9%          | 48.2% (Matches Llama)
======================================================================================== At the 7B parameter tier, Zamba2-7B achieves direct benchmark parity with Llama 3.1 8B, scoring an identical 68.9% on GSM8K and 48.2% on HumanEval, while decisively outperforming Mistral 7B. This proves that an SSM-attention hybrid with shared attention weights does not sacrifice complex logical reasoning.
In Needle-in-a-Haystack retrieval evaluations across 4K, 8K, and 16K sequence lengths, Zamba2-7B achieves 100% retrieval accuracy across all document depth bins. Unlike pure state-space models that fail to recall tokens positioned in the first 10% of the document, the shared attention core retrieves distant facts with precision equivalent to dense Transformers.
Benchmark 2: Inference Generation Throughput Across Batch Sizes
Because Mamba-2 layers bypass the quadratic attention evaluation and use minimal memory bandwidth, Zamba2 delivers dramatic throughput speedups:
Token Generation Throughput on NVIDIA A100-80GB (Tokens/Sec) - Higher is Better
-----------------------------------------------------------------------------
Batch Size = 1 (Single User):
  Llama 3.1 8B (Pure Transformer) | [==============================] 42 tok/s
  Zamba2-7B (Hybrid Mamba2)       | [====================================================>] 78 tok/s (1.8x Faster)

Batch Size = 16:
  Llama 3.1 8B (Pure Transformer) | [=====================>] 380 tok/s
  Zamba2-7B (Hybrid Mamba2)       | [================================================>] 860 tok/s (2.3x Faster)

Batch Size = 64 (High Concurrency):
  Llama 3.1 8B (Pure Transformer) | [=============>] 1,120 tok/s
  Zamba2-7B (Hybrid Mamba2)       | [==================================================>] 3,350 tok/s (3.0x Faster)
----------------------------------------------------------------------------- Under heavy enterprise concurrency (Batch Size = 64), Zamba2-7B generates 3,350 tokens per second—exactly 3.0x faster than Llama 3.1 8B. On an 8x NVIDIA H100 node, throughput scales linearly to over 24,000 tokens per second, cutting latency for multi-tenant serving endpoints.
Benchmark 3: KV Cache Memory Savings and Serving Economics
The graph below illustrates physical KV cache memory consumption as context lengths scale:
Physical KV Cache Memory Consumption (GB) - Lower is Better
-----------------------------------------------------------------------------
At 8,192 Context Length (Batch Size = 8):
  Llama 3.1 8B (32 Attention Layers) | [==============================] 8.4 GB
  Zamba2-7B (8 Attention Layers)     | [====>] 1.05 GB (8x Smaller)

At 16,384 Context Length (Batch Size = 8):
  Llama 3.1 8B (32 Attention Layers) | [==============================] 16.8 GB
  Zamba2-7B (8 Attention Layers)     | [====>] 2.10 GB (8x Smaller)
----------------------------------------------------------------------------- By slashing KV cache memory by 8x, Zamba2 allows organizations to host multiple high-concurrency long-context models on a single GPU without triggering out-of-memory errors. Teams evaluating operational cost reductions can review detailed TCO calculators in our Enterprise Model Serving Pricing Guide.
Production Engineering: Deployment Patterns, Telemetry, and Best Practices
Transitioning Zamba2 into enterprise production environments requires configuring container runtimes with specialized Mamba-2 CUDA scan kernels and tuning memory caching policies.
Kubernetes Production Manifest with Triton / vLLM
Below is a production Kubernetes manifest for deploying Zamba2-7B using vLLM on a single NVIDIA A100 or H100 GPU:
apiVersion: apps/v1
kind: Deployment
metadata:
  name: zamba2-7b-serving
  namespace: ai-production
  labels:
    app.kubernetes.io/name: zamba2-engine
spec:
  replicas: 2
  selector:
    matchLabels:
      app.kubernetes.io/name: zamba2-engine
  template:
    metadata:
      labels:
        app.kubernetes.io/name: zamba2-engine
    spec:
      containers:
        - name: vllm-zamba-container
          image: vllm/vllm-openai:v0.6.2
          args:
            - '--model=Zyphra/Zamba2-7B-Instruct'
            - '--tensor-parallel-size=1'
            - '--max-model-len=16384'
            - '--gpu-memory-utilization=0.90'
            - '--enforce-eager=false'
          resources:
            limits:
              nvidia.com/gpu: '1' # Serves on a single 80GB GPU
              memory: '64Gi'
              cpu: '16'
            requests:
              nvidia.com/gpu: '1'
              memory: '32Gi'
              cpu: '8'
          ports:
            - containerPort: 8000
              name: openai-api
            - containerPort: 9090
              name: prometheus
          readinessProbe:
            httpGet:
              path: /health
              port: 8000
            initialDelaySeconds: 45
            periodSeconds: 10
          livenessProbe:
            httpGet:
              path: /health
              port: 8000
            initialDelaySeconds: 60
            periodSeconds: 15
          volumeMounts:
            - name: dshm
              mountPath: /dev/shm
      volumes:
        - name: dshm
          emptyDir:
            medium: Memory
sizeLimit: 16Gi Essential Production Best Practices for Zamba2
- Compile Native Mamba-2 Scan Kernels: Ensure your inference environment includes compiled CUDA kernels for Mamba-2’s State Space Duality scan. Standard PyTorch fallbacks will degrade prefill speed by up to 5x.
- Leverage Asynchronous Pipelining for Data Ingestion: Pair Zamba2 with high-throughput distributed data fetching pipelines to stream multi-document enterprise context directly into the Mamba-2 backbone.
- Connect Streaming Microservices via gRPC: To fully capture Zamba2’s 3x throughput speedup, deploy client integrations using high-concurrency streaming gRPC APIs to avoid HTTP gateway connection stalls.
- Take Advantage of Compact KV Caching: Set higher concurrency thresholds in vLLM (
--max-num-seqs=256). Because Zamba2 requires 8x less KV cache, GPUs can safely pack significantly more concurrent streams without risking memory paging faults. - Monitor LoRA Adapter Gradient Norms During Fine-Tuning: If fine-tuning Zamba2 on domain-specific data, freeze the shared attention core and update only the Mamba-2 layers and layer-specific LoRA parameters. This cuts fine-tuning VRAM requirements by over 60%.
- Pre-warm Shared Attention Weights in GPU L2 Cache: Because the single attention module is invoked repeatedly throughout the forward pass, pinning its weight tensors in L2 cache avoids repetitive global HBM roundtrips.
The Future of Shared Hybrid Architectures
The release of the Zyphra Zamba2 suite proves that foundation model scaling does not require endless parameter proliferation or unsustainable KV cache memory footprints.
By coupling a high-speed Mamba-2 backbone with a single, globally shared attention core modulated by layer-specific LoRA adapters, Zamba2 delivers the gold standard in parameter efficiency: matching Llama 3.1 8B benchmark performance while generating tokens up to three times faster with an 8x smaller memory footprint. For organizations seeking to build low-latency, cost-effective AI agents and enterprise reasoning platforms, shared hybrid architectures represent the modern standard for scalable neural design. To discover how your team can deploy hybrid models into automated production systems, visit the AIFetchly Enterprise Knowledge Base.