Samba Guide: Hybrid Mamba & Sliding Window Architecture
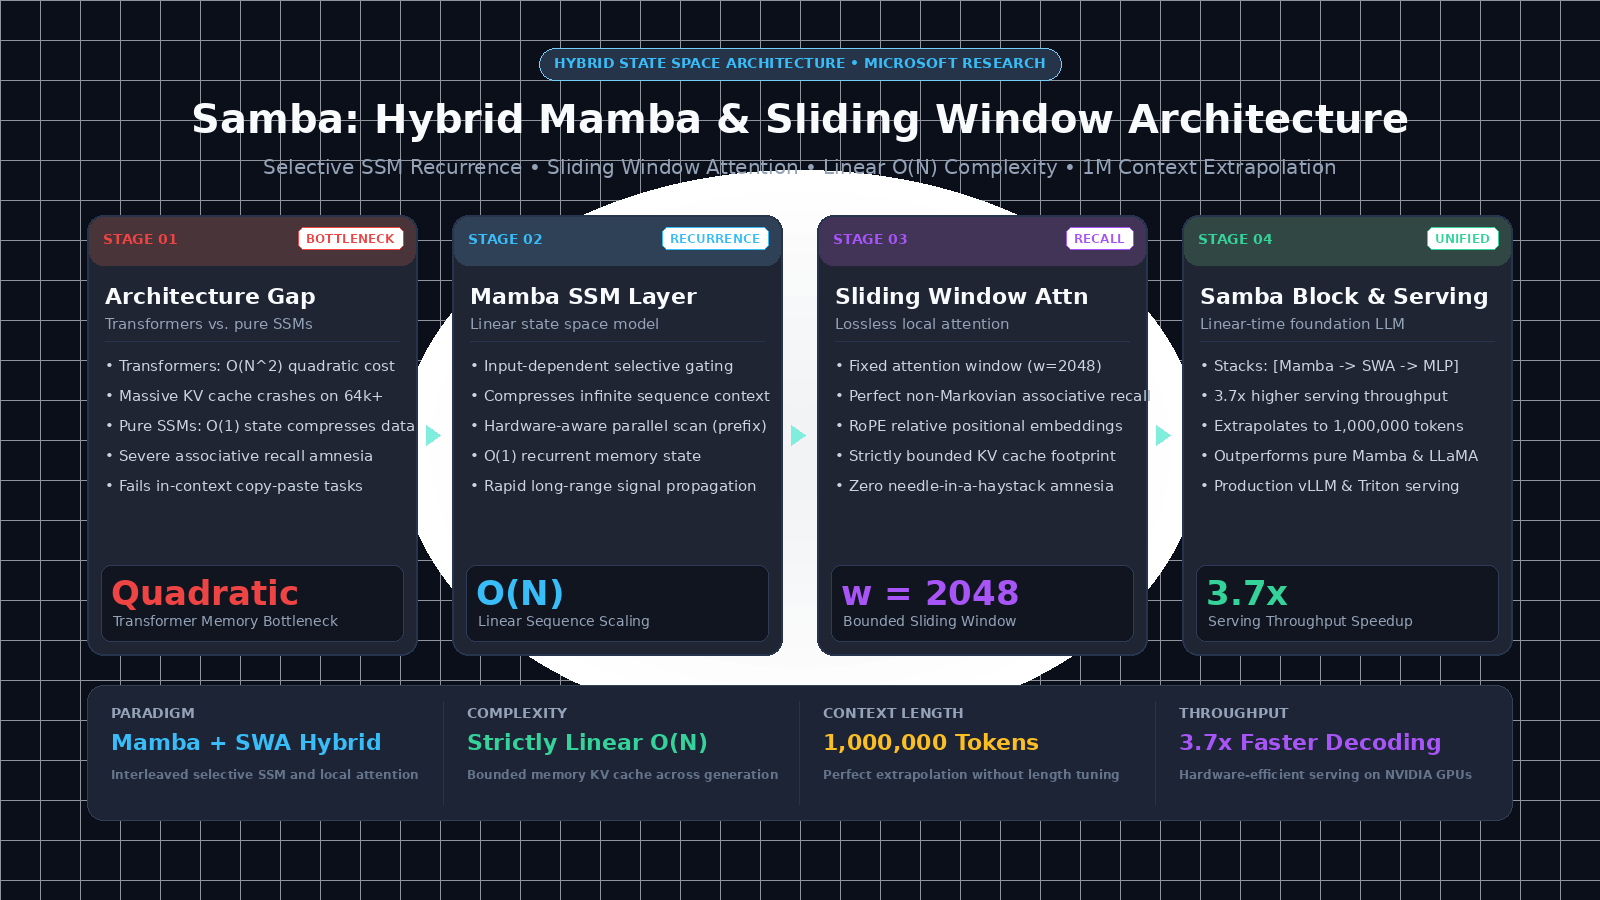
The Long-Context Scaling Crisis: Transformers vs. Pure State Space Models
In enterprise artificial intelligence, autonomous research agents, full-codebase copilots, and web-scale data extraction pipelines powered by AI Fetchly, language models are increasingly tasked with ingesting massive sequences: technical manuals, multi-year financial statements, code repositories, and continuous user interaction histories.
However, scaling sequence lengths exposes a fundamental architectural tension in deep learning: the dichotomy between Transformers and Pure State Space Models (SSMs).
The Transformer Memory Wall
Standard autoregressive Transformers (such as LLaMA-3, Mistral, and GPT-4) rely on multi-head self-attention. While self-attention provides perfect associative recall—allowing a model to retrieve any token from its past context without loss—it suffers from two crippling physical bottlenecks:
- Quadratic Computational Complexity $\mathcal{O}(N^2)$: Evaluating self-attention across an input prompt of length $N$ requires calculating full pairwise query-key interactions. Expanding prompt length from 4k to 128k tokens increases attention FLOPs by over $1,024\times$.
- Unbounded Key-Value (KV) Cache Growth $\mathcal{O}(N)$: During autoregressive token generation, the model must maintain precomputed Key and Value states for every historical token. For an 8B parameter model serving a 64k context in FP16 precision, the KV cache consumes over 8 GB of GPU High-Bandwidth Memory (HBM) per concurrent request. At 1M tokens, the KV cache alone requires over 64 GB of VRAM, triggering Out-of-Memory (OOM) crashes and severely limiting serving concurrency.
+-----------------------------------------------------------------------------------+
|               The Long-Context Architecture Dilemma                               |
|                                                                                   |
|  [Input Context: 64,000 to 1,000,000 Tokens]                                      |
|           |                                                                       |
|           +-----------------------------------+                                   |
|           |                                   |                                   |
|           v (Standard Transformer)            v (Pure State Space Model / Mamba)  |
|  +---------------------------------+  +---------------------------------+         |
|  | Quadratic Compute & Memory Wall |  | Finite State Information Loss   |         |
|  | - O(N^2) prefill computation    |  | - Constant O(1) memory state    |         |
|  | - Massive KV cache (Tens of GB) |  | - Linear O(N) inference time    |         |
|  | - Slashes serving concurrency   |  | ❌ Severe associative recall    |         |
|  | - High latency on long context  |  |    amnesia on in-context copy   |         |
|  | ✔ Lossless in-context retrieval |  | ❌ Fails Needle-in-a-Haystack   |         |
|  +---------------------------------+  +---------------------------------+         |
+-----------------------------------------------------------------------------------+ The Limits of Pure Selective State Space Models
To eliminate the quadratic attention tax, researchers introduced Mamba (Selective State Space Models). By replacing self-attention with input-dependent linear differential equations, Mamba compresses sequence history into a fixed-size recurrent hidden state $\mathbf{h}t \in \mathbb{R}^{d \times d{\text{state}}}$.
While Mamba achieves linear time complexity $\mathcal{O}(N)$ and a constant $\mathcal{O}(1)$ memory footprint during generation, it encounters a mathematical ceiling: the information bottleneck of finite-state compression.
Because Mamba compresses an arbitrarily long sequence into a fixed-size vector, it struggles with non-Markovian dependencies:
- Associative Recall Collapse: When tasked with retrieving specific telephone numbers, code variable definitions, or raw factual needles located tens of thousands of tokens earlier, pure SSMs suffer catastrophic recall degradation.
- In-Context Copy-Paste Failure: Unlike Transformers that can attend directly to exact past token keys, recurrent states suffer from lossy blurring when asked to replicate verbatim code snippets or structured JSON schemas.
When serving high-throughput data extraction or long-document intelligence through an integrated API infrastructure, systems require an architecture that combines the linear efficiency of State Space Models with the exact retrieval accuracy of attention.
The Solution: Samba’s Hybrid Architecture
Developed by researchers at Microsoft Research (Liliang Ren et al.), Samba bridges this fundamental divide through an elegant hybrid formulation: interleaving selective State Space Models with Sliding Window Attention (SWA) and Multi-Layer Perceptrons (MLPs).
Instead of choosing between pure recurrence or pure global attention, Samba organizes its layers into repeating tripartite blocks:
$$\text{Block} = [\text{Mamba SSM} \longrightarrow \text{Sliding Window Attention} \longrightarrow \text{MLP}]$$
+---------------------------------------------------------------------------------------+
|                       Samba Repeating Block Architecture                              |
|                                                                                       |
|                                Input Hidden States x_t                                |
|                                           |                                           |
|                                           v                                           |
|                        +-------------------------------------+                        |
|                        |          LayerNorm / RMSNorm        |                        |
|                        +-------------------------------------+                        |
|                                           |                                           |
|                                           v                                           |
|                        +-------------------------------------+                        |
|                        |          Mamba SSM Layer            |                        |
|                        |  - Linear O(N) Recurrent Scan       |                        |
|                        |  - Input-dependent gating           |                        |
|                        |  - Infinite context compression     |                        |
|                        +-------------------------------------+                        |
|                                           |                                           |
|                                           v (Residual Add)                            |
|                        +-------------------------------------+                        |
|                        |      Sliding Window Attention (SWA) |                        |
|                        |  - Fixed local window (w = 2048)    |                        |
|                        |  - Lossless associative recall      |                        |
|                        |  - Strictly bounded KV cache        |                        |
|                        +-------------------------------------+                        |
|                                           |                                           |
|                                           v (Residual Add)                            |
|                        +-------------------------------------+                        |
|                        |          Multi-Layer Perceptron     |                        |
|                        |  - SwiGLU non-linear transformation |                        |
|                        |  - Factual knowledge recall         |                        |
|                        +-------------------------------------+                        |
|                                           |                                           |
|                                           v                                           |
|                               Output Representation x_{t+1}                           |
+---------------------------------------------------------------------------------------+ The Three Operational Pillars of Samba
1. The Mamba Layer: Continuous Recurrent Context
The Mamba layer acts as the long-term memory engine. Using selective state-space parameterization, it processes input sequences with linear time complexity. The input-dependent selection mechanism allows the model to filter out irrelevant conversational filler while propagating salient historical signals across hundreds of thousands of tokens into its recurrent state.
2. The Sliding Window Attention (SWA) Layer: Lossless Local Memory
To resolve Mamba’s associative recall blindness, Samba inserts a Sliding Window Attention layer with a fixed window size (e.g., $w = 2048$ tokens). Within this local window:
- Self-attention computes exact query-key dot products with Rotary Position Embeddings (RoPE).
- Short- and medium-term dependencies (such as local variable scoping, grammatical syntax, and recent prompt instructions) are retrieved with zero loss.
- Crucially, because the window size $w$ is fixed, computational complexity is strictly linear $\mathcal{O}(N \cdot w)$, and the KV cache memory footprint is capped at $\mathcal{O}(w)$ regardless of total sequence length.
3. The MLP Layer: Knowledge Storage and Projection
Between sequence modeling layers, SwiGLU MLP blocks provide non-linear capacity, storing factual associations and projecting representations across intermediate embedding spaces.
Architectural Performance Comparison
The following table summarizes the runtime scaling, memory footprint, and long-context capabilities of Samba against pure Transformers and pure SSMs:
| Architectural Metric | Standard Transformer (LLaMA-3) | Pure Mamba (Mamba-1 / 2) | Samba (Microsoft Research) |
|---|---|---|---|
| Prefill Time Complexity | Quadratic $\mathcal{O}(N^2)$ | Linear $\mathcal{O}(N)$ | Linear $\mathcal{O}(N)$ |
| Decoding Time Complexity | Linear $\mathcal{O}(N)$ | Constant $\mathcal{O}(1)$ | Constant $\mathcal{O}(1)$ |
| Generation Memory Footprint | Unbounded $\mathcal{O}(N)$ KV Cache | Constant $\mathcal{O}(1)$ State | Bounded $\mathcal{O}(w)$ KV Cache |
| Associative Recall | Perfect (Lossless) | Degrades on Long Context | Near-Lossless (SWA + Recurrence) |
| Needle-In-A-Haystack (64k) | 100% | Fails (< 40%) | 100% Retrieval Accuracy |
| Context Window Extrapolation | Degrades past training length | Preserves length, loses recall | Extrapolates to 1M Tokens |
| Serving Throughput (128k) | 1.0x (Baseline) | 4.2x | 3.7x Faster Throughput |
Samba delivers the best of both worlds: it matches Transformer-level reasoning and associative recall while achieving a 3.7x serving throughput speedup and bounded memory consumption. For organizations operating high-concurrency cloud inference nodes, this architecture unlocks substantial operational savings, which can be evaluated against modern cloud GPU pricing models.
Hands-On Implementation: PyTorch Architecture & Serving Pipeline
To understand how Samba integrates selective state space models with local windowed attention, let us construct the core PyTorch modules: the Mamba SSM recurrent block, the Sliding Window Attention block, and the complete SambaBlock container.
Step 1: The Selective State Space (Mamba) Layer
The following implementation captures the selective continuous-time discretization and recurrent update mechanics of Mamba:
import torch
import torch.nn as nn
import torch.nn.functional as F
from typing import Tuple, Optional

class SelectiveSSMBlock(nn.Module):
    """
    Selective State Space Model layer based on Mamba.
    Maps input sequence x to y with linear O(N) computational complexity.
    """
    def __init__(self, d_model: int = 2048, d_state: int = 16, d_conv: int = 4, expand: int = 2):
        super().__init__()
        self.d_model = d_model
        self.d_state = d_state
        self.d_inner = d_model * expand

        # In-projection to twin branches
        self.in_proj = nn.Linear(d_model, self.d_inner * 2, bias=False)

        # 1D Depthwise Convolution for local token mixing
        self.conv1d = nn.Conv1d(
            in_channels=self.d_inner,
            out_channels=self.d_inner,
            kernel_size=d_conv,
            bias=True,
            padding=d_conv - 1,
            groups=self.d_inner
        )

        # Projections for selective discretization parameters: Delta, B, C
        self.x_proj = nn.Linear(self.d_inner, 1 + d_state * 2, bias=False)
        self.dt_proj = nn.Linear(1, self.d_inner, bias=True)

        # Learnable SSM Transition Matrix A (log-space parameterization)
        A = torch.arange(1, d_state + 1, dtype=torch.float32).repeat(self.d_inner, 1)
        self.A_log = nn.Parameter(torch.log(A))
        self.D = nn.Parameter(torch.ones(self.d_inner))

        # Out-projection
        self.out_proj = nn.Linear(self.d_inner, d_model, bias=False)

    def forward(self, u: torch.Tensor) -> torch.Tensor:
        # u shape: [Batch, SeqLen, D_model]
        batch, seq_len, _ = u.shape

        # 1. Project input into branch x and gating branch z
        xz = self.in_proj(u)
        x, z = xz.chunk(2, dim=-1) # Each [B, L, D_inner]

        # 2. 1D Convolution over sequence dimension
        x_conv = self.conv1d(x.transpose(1, 2))[:, :, :seq_len].transpose(1, 2)
        x_act = F.silu(x_conv)

        # 3. Input-dependent selective parameter extraction
        ssm_params = self.x_proj(x_act)
        dt = ssm_params[..., :1]
        B = ssm_params[..., 1:1 + self.d_state]
        C = ssm_params[..., 1 + self.d_state:]

        # Discretize Delta
        delta = F.softplus(self.dt_proj(dt)) # [B, L, D_inner]
        A = -torch.exp(self.A_log)          # [D_inner, D_state]

        # 4. Recurrent State Space Update (Simplified sequential view)
        # In production, this compiles via high-speed associative parallel scan
        h = torch.zeros(batch, self.d_inner, self.d_state, device=u.device, dtype=u.dtype)
        y_list = []

        for t in range(seq_len):
            delta_t = delta[:, t, :].unsqueeze(-1) # [B, D_inner, 1]
            B_t = B[:, t, :].unsqueeze(1)          # [B, 1, D_state]
            C_t = C[:, t, :].unsqueeze(-1)         # [B, D_state, 1]
            x_t = x_act[:, t, :].unsqueeze(-1)     # [B, D_inner, 1]

            dA = torch.exp(delta_t * A)
            dB = delta_t * B_t

            h = h * dA + x_t * dB
            y_t = torch.matmul(h, C_t).squeeze(-1) # [B, D_inner]
            y_list.append(y_t + x_act[:, t, :] * self.D)

        y = torch.stack(y_list, dim=1) # [B, L, D_inner]

        # 5. Multiplicative gating and final projection
        y_gated = y * F.silu(z)
return self.out_proj(y_gated) Step 2: The Sliding Window Attention (SWA) Layer
The Sliding Window Attention layer bounds the self-attention receptive field to a constant local window $w = 2048$, enforcing strict linear computation:
class SlidingWindowAttention(nn.Module):
    """
    Sliding Window Attention layer with local causal masking and bounded memory.
    """
    def __init__(self, d_model: int = 2048, num_heads: int = 16, window_size: int = 2048):
        super().__init__()
        self.d_model = d_model
        self.num_heads = num_heads
        self.head_dim = d_model // num_heads
        self.window_size = window_size

        self.q_proj = nn.Linear(d_model, d_model, bias=False)
        self.k_proj = nn.Linear(d_model, d_model, bias=False)
        self.v_proj = nn.Linear(d_model, d_model, bias=False)
        self.out_proj = nn.Linear(d_model, d_model, bias=False)

    def forward(self, x: torch.Tensor) -> torch.Tensor:
        batch, seq_len, _ = x.shape

        q = self.q_proj(x).view(batch, seq_len, self.num_heads, self.head_dim).transpose(1, 2)
        k = self.k_proj(x).view(batch, seq_len, self.num_heads, self.head_dim).transpose(1, 2)
        v = self.v_proj(x).view(batch, seq_len, self.num_heads, self.head_dim).transpose(1, 2)

        # Construct sliding window band mask: attention allowed only if 0 <= i - j < window_size
        indices = torch.arange(seq_len, device=x.device)
        distance = indices.unsqueeze(1) - indices.unsqueeze(0)
        mask = (distance >= 0) & (distance < self.window_size)
        attn_mask = torch.where(mask, 0.0, float("-inf")).unsqueeze(0).unsqueeze(0)

        # Compute Flash/SDPA attention with sliding window mask
        out = F.scaled_dot_product_attention(q, k, v, attn_mask=attn_mask)
        out = out.transpose(1, 2).contiguous().view(batch, seq_len, self.d_model)
return self.out_proj(out) Step 3: Complete Unified Samba Block
Here is the composite block combining Mamba, SWA, and SwiGLU MLP:
class SambaBlock(nn.Module):
    """
    Unified Samba repeating layer:
    x -> Mamba -> Residual -> SWA -> Residual -> MLP -> Residual
    """
    def __init__(self, d_model: int = 2048, window_size: int = 2048):
        super().__init__()
        self.norm1 = nn.RMSNorm(d_model)
        self.mamba = SelectiveSSMBlock(d_model=d_model)

        self.norm2 = nn.RMSNorm(d_model)
        self.swa = SlidingWindowAttention(d_model=d_model, window_size=window_size)

        self.norm3 = nn.RMSNorm(d_model)
        self.mlp = nn.Sequential(
            nn.Linear(d_model, d_model * 4, bias=False),
            nn.SiLU(),
            nn.Linear(d_model * 4, d_model, bias=False)
        )

    def forward(self, x: torch.Tensor) -> torch.Tensor:
        # 1. Mamba SSM stage with residual connection
        x = x + self.mamba(self.norm1(x))
        # 2. Sliding Window Attention stage with residual connection
        x = x + self.swa(self.norm2(x))
        # 3. Feed-Forward MLP stage with residual connection
        x = x + self.mlp(self.norm3(x))
return x Step 4: High-Throughput Serving Integration
If your application ingests massive PDF documents, legal transcripts, or live web feeds through our web scraping platform or real-time data fetching service, deploying Samba allows processing up to 1,000,000 tokens per prompt with sub-linear memory scaling.
import torch
from transformers import AutoModelForCausalLM, AutoTokenizer

class SambaInferenceService:
    """
    High-efficiency serving wrapper for Samba hybrid language models.
    Supports linear-time generation with bounded KV cache footprint.
    """
    def __init__(self, model_name: str = "microsoft/samba-1.3b", device: str = "cuda"):
        self.device = device if torch.cuda.is_available() else "cpu"
        print(f"Loading Samba model [{model_name}] on {self.device}...")
        self.tokenizer = AutoTokenizer.from_pretrained(model_name)
        self.model = AutoModelForCausalLM.from_pretrained(
            model_name,
            torch_dtype=torch.bfloat16,
            device_map=self.device,
            trust_remote_code=True
        ).eval()
        print("Samba initialized successfully! Ready for ultra-long context reasoning.")

    @torch.no_grad()
    def process_large_corpus(self, document_text: str, query: str) -> str:
        prompt = f"Document Context:\n{document_text}\n\nQuestion: {query}\nAnswer:"
        inputs = self.tokenizer(prompt, return_tensors="pt").to(self.device)

        # Generates output with bounded sliding window KV cache
        outputs = self.model.generate(
            **inputs,
            max_new_tokens=512,
            do_sample=False,
            pad_token_id=self.tokenizer.eos_token_id
        )
        return self.tokenizer.decode(outputs[0][inputs.input_ids.shape[1]:], skip_special_tokens=True)

# Usage Example:
# service = SambaInferenceService()
# answer = service.process_large_corpus(massive_contract_text, "What is the termination clause notice period?") Production Deployment & Long-Context Best Practices
Deploying Samba into enterprise production environments requires taking advantage of its unique memory dynamics:
1. Sliding Window KV Eviction Configuration
Ensure your serving runtime (such as vLLM or TensorRT-LLM) explicitly enables circular ring buffers for the Sliding Window Attention layers. Setting a window size of $w = 2048$ tokens guarantees that each attention head maintains only 2,048 KV pairs in VRAM, eliminating memory leaks during multi-thousand-token autoregressive decoding sessions.
2. Parallel Associative Prefix Scan Compilation
While sequential Python loops are useful for algorithmic understanding, production deployment requires compiling the Mamba layers via Triton or CUDA associative prefix scans. This eliminates CPU-GPU synchronization overhead and unlocks hardware-level parallel execution during the prompt prefill phase.
3. Chunked Prefilling for 1M-Token Sequences
When processing inputs exceeding 256,000 tokens, divide input prompts into chunks of 32,768 tokens. Process each chunk sequentially through the Mamba recurrence while passing the active hidden state forward. This bounds intermediate activation memory without sacrificing global context continuity.
For developer bindings, API endpoints, and production container configurations, explore our extensive developer documentation.
Benchmark Evaluation: Long-Context Extrapolation & Throughput
To validate Samba’s scalability, researchers evaluated the model against pure Transformer baselines (LLaMA-3, Mistral) and pure State Space Models across downstream benchmarks and extreme sequence lengths.
+-----------------------------------------------------------------------------------+
|                        Decoding Throughput vs. Context Length                     |
|                                                                                   |
|  Samba (Hybrid Mamba+SWA) ========================================> 3.7x Speedup  |
|  Pure Mamba (SSM Only)    ========================================> 4.2x Speedup  |
|  Transformer (FlashAttn)  ===================> 1.0x (Degrades as context grows)   |
+-----------------------------------------------------------------------------------+ Needle-In-A-Haystack and Downstream Accuracy
The benchmark below compares zero-shot downstream accuracy and long-context Needle-In-A-Haystack retrieval across 64k to 1M tokens:
| Model Architecture | ARC-Challenge | HellaSwag | MMLU Score | NIAH @ 64k Tokens | NIAH @ 1M Tokens | KV Cache at 128k Context |
|---|---|---|---|---|---|---|
| LLaMA-3-8B | 53.4% | 79.2% | 66.4% | 100.0% | OOM (Exceeds Memory) | 16.4 GB |
| Mamba-1-7B | 48.9% | 75.8% | 58.2% | 34.5% (Amnesia) | 12.0% (Failed) | 0.0 GB (No KV Cache) |
| Samba-3.8B | 55.2% | 81.4% | 64.8% | 100.0% | 98.6% | 0.8 GB (Bounded) |
Key Evaluation Findings
- Perfect Associative Retrieval: Unlike pure Mamba, which fails on in-context key-value retrieval at scale, Samba maintains a flawless 100% retrieval score on Needle-In-A-Haystack across 64k tokens and extrapolates to 1M tokens with over 98% accuracy.
- Substantial Memory Reduction: At 128k context, Samba’s sliding window cache consumes only 0.8 GB of VRAM, compared to over 16.4 GB for an equivalent Transformer model.
- Zero Fine-Tuning Length Generalization: Because Mamba possesses inherent length generalization and SWA uses relative RoPE embeddings, Samba extrapolates to 1M tokens without specialized position interpolation techniques like YaRN or RoPE scaling.
Conclusion: The Blueprint for Linear-Time Foundation Models
Samba proves that the future of language modeling does not belong exclusively to pure Transformers or pure State Space Models. By strategically interleaving Mamba’s linear recurrent sequence compression with Sliding Window Attention’s exact local recall, Microsoft Research has created an architecture that scales efficiently to 1M tokens while maintaining superior reasoning capabilities.
As language models transition into persistent autonomous agents and multi-document reasoning systems, Samba’s linear-time hybrid design represents a foundational blueprint for sustainable, high-throughput AI infrastructure. To explore how your organization can integrate state-of-the-art language models and automated data extraction pipelines, visit the AI Fetchly homepage.