Jamba 1.5 Guide: Hybrid SSM-Transformer MoE AI
The Quadratic Bottleneck and the Long-Context KV Cache Crisis
Over the past decade, the standard Transformer architecture has powered the foundation model revolution. Its self-attention mechanism provides an unmatched inductive bias for in-context learning, capturing complex multi-token dependencies and semantic associations across heterogeneous modalities. However, as enterprise AI applications shift from short conversational turns to extensive reasoning workloads—such as full-repository code audits, multi-hundred-page financial filings, clinical dossier synthesis, and autonomous agent history trees—the structural limitations of standard self-attention have become critical operational barriers.
In a canonical dense Transformer model, the computational complexity of self-attention scales quadratically ($\mathcal{O}(N^2)$) with sequence length $N$. Computing pairwise dot products between query vectors and all preceding key vectors requires $N^2$ multiplications per attention head per layer. While modern FlashAttention kernels and tiled memory hierarchies mitigate the arithmetic latency during the prefill phase, they cannot circumvent the physical memory storage dilemma that emerges during autoregressive token generation.
During the decoding phase, every generated token attends back to all historical tokens. To prevent redundant computation, inference engines persist all prior key and value projection tensors in high-bandwidth memory (HBM)—a structure known as the Key-Value (KV) cache. The physical memory required to store this cache scales linearly with sequence length, batch concurrency, and layer depth:
$$\text{KV Cache Size} = 2 \times B \times L \times H_{\text{kv}} \times D_{\text{head}} \times N \times P$$
Where:
- $B$ is the batch size (concurrent requests).
- $L$ is the number of transformer layers.
- $H_{\text{kv}}$ is the number of key-value heads.
- $D_{\text{head}}$ is the head dimension.
- $N$ is the context sequence length.
- $P$ is the numerical precision byte size (e.g., 2 bytes for FP16/BF16).
In massive context windows such as 128,000 or 256,000 tokens, the KV cache footprint quickly eclipses the memory required to hold the model weights themselves. For example, serving a standard dense 70B model with a 256K token context consumes approximately 32 gigabytes of HBM per single sequence. Under modest enterprise concurrency—such as serving a batch of 16 concurrent analysts or automated intelligent web scraping workflows—the KV cache demands over 500 gigabytes of accelerator memory. This forces engineering teams to deploy sprawling, multi-GPU clusters solely to avoid out-of-memory (OOM) errors, leaving expensive tensor computing cores drastically underutilized.
Furthermore, state-space models (SSMs) like Mamba have emerged as an alluring alternative, offering linear computational complexity ($\mathcal{O}(N)$) and constant-size recurrence states ($\mathcal{O}(1)$). However, pure SSMs struggle with high-capacity associative recall, complex multi-hop reasoning, and “needle-in-a-haystack” retrieval over extended contexts. When processing multi-document enterprise knowledge bases, pure SSMs frequently suffer from memory degradation, fading attention to tokens located tens of thousands of positions in the past.
Modern enterprise systems require an architecture that unites the near-infinite associative recall of self-attention with the linear computational efficiency and constant state footprint of recurrent state-space models.
The Jamba 1.5 Architecture: Strategic Hybridization at Scale
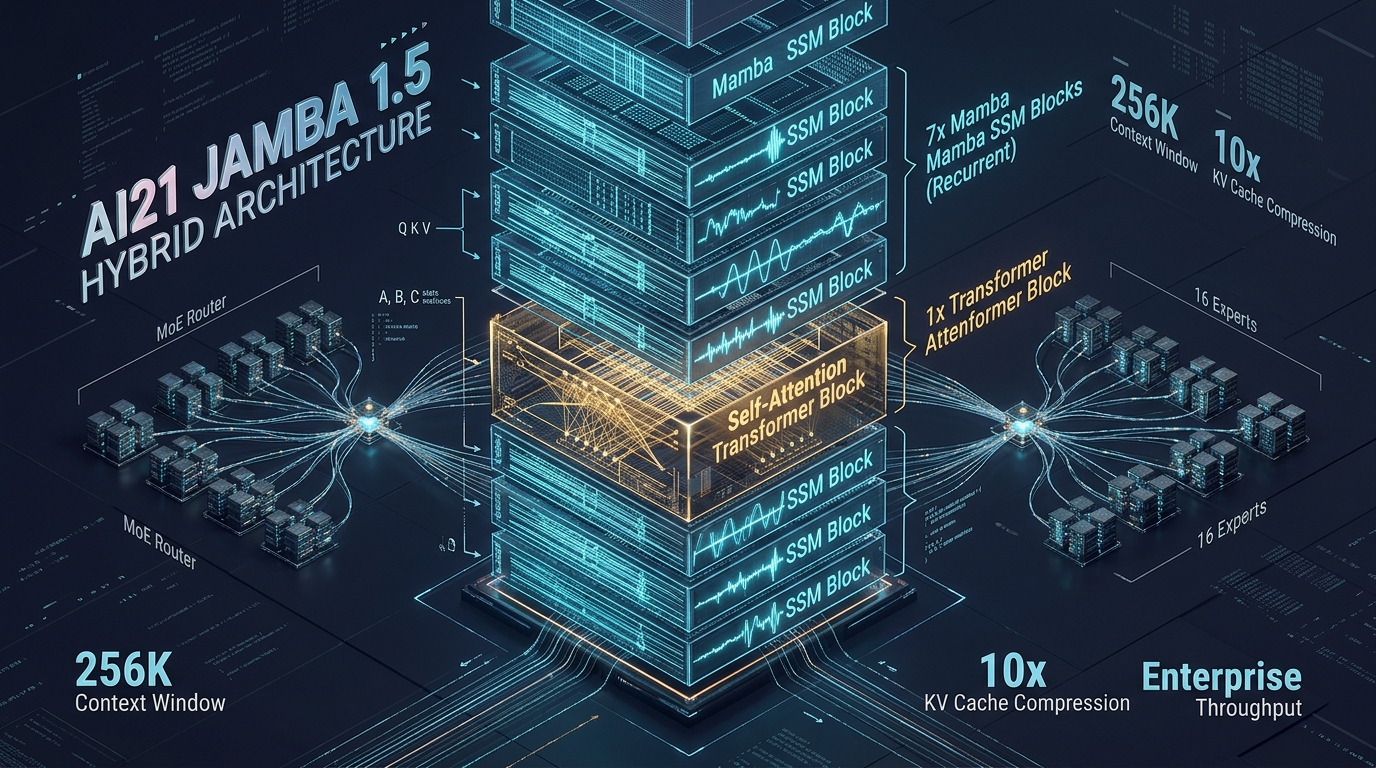
Developed by AI21 Labs, the Jamba 1.5 model family (comprising Jamba 1.5 Mini and Jamba 1.5 Large) represents a breakthrough in foundation model design. Rather than treating Transformers and State Space Models as mutually exclusive alternatives, Jamba 1.5 introduces a principled, deeply integrated hybrid architecture that resolves the memory wall through three foundational innovations:
- Strategic Layer Interleaving (The 7:1 Mamba-to-Attention Ratio): Jamba 1.5 interleaves Mamba SSM layers and standard Multi-Head Attention layers in a precise repeating ratio. For every 8 consecutive layers, 7 layers are linear Mamba blocks and only 1 layer is a full Transformer self-attention block.
- Sparse Mixture-of-Experts (MoE) Feed-Forward Networks: Every layer (both Mamba and Attention) employs a sparse 16-expert feed-forward network with top-2 expert routing, dramatically scaling parameter capacity while keeping per-token floating-point execution costs bounded.
- Native ExpertsInt8 Quantization: Jamba 1.5 integrates INT8 quantization natively across its MoE expert layers during both pre-training and inference runtimes, enabling a 398-billion parameter model to run efficiently on standard enterprise hardware without quality degradation.
+-----------------------------------------------------------------------------------------+
|                              JAMBA 1.5 LAYER INTERLEAVING PATTERN                       |
+-----------------------------------------------------------------------------------------+
|                                                                                         |
|   +---------------------------------------------------------------------------------+   |
|   |  Mamba SSM Block 1   (Linear O(N) Complexity | Zero KV Cache Allocation)        |   |
|   +---------------------------------------------------------------------------------+   |
|   |  Mamba SSM Block 2   (Linear O(N) Complexity | Zero KV Cache Allocation)        |   |
|   +---------------------------------------------------------------------------------+   |
|   |  Mamba SSM Block 3   (Linear O(N) Complexity | Zero KV Cache Allocation)        |   |
|   +---------------------------------------------------------------------------------+   |
|   |  Mamba SSM Block 4   (Linear O(N) Complexity | Zero KV Cache Allocation)        |   |
|   +---------------------------------------------------------------------------------+   |
|   |  Mamba SSM Block 5   (Linear O(N) Complexity | Zero KV Cache Allocation)        |   |
|   +---------------------------------------------------------------------------------+   |
|   |  Mamba SSM Block 6   (Linear O(N) Complexity | Zero KV Cache Allocation)        |   |
|   +---------------------------------------------------------------------------------+   |
|   |  Mamba SSM Block 7   (Linear O(N) Complexity | Zero KV Cache Allocation)        |   |
|   +---------------------------------------------------------------------------------+   |
|   |  Self-Attention Block 8 (Quadratic O(N^2) | Allocates Standard KV Cache)        |   |
|   +---------------------------------------------------------------------------------+   |
|                                                                                         |
|   [ Result: KV Cache Memory Reduced by Up to 10x | Context Length Scaled to 256K ]     |
+-----------------------------------------------------------------------------------------+ Because 7 out of every 8 layers do not allocate key-value cache tensors, the total KV cache memory requirement of Jamba 1.5 is slashed by up to ten times compared to a dense Transformer of equivalent size. The Mamba layers continuously compress and propagate contextual representations through compact hidden state vectors, while the periodic attention layers preserve needle-sharp retrieval accuracy across massive sequence lengths.
On the rigorous RULER benchmark—which stress-tests model retrieval across diverse document structures—Jamba 1.5 stands as the only publicly available open-weight model family that maintains flawless retrieval across its entire 256,000-token context window.
Architectural Deep Dive: Mathematical Formulation and Structural Topology
The Jamba 1.5 architecture combines three complementary mathematical regimes into a cohesive transformer block: Mamba state-space recurrence, scaled dot-product attention, and sparse expert routing.
Mamba State-Space Layers: Continuous-Time Recurrence and Selective Discretization
The linear layers in Jamba 1.5 are based on the selective state-space model formulation. Continuous-time state-space models map a continuous 1D input signal $x(t) \in \mathbb{R}$ to an output $y(t) \in \mathbb{R}$ through an intermediate latent state $h(t) \in \mathbb{R}^n$:
$$
\begin{aligned}
h’(t) &= \mathbf{A} h(t) + \mathbf{B} x(t)
y(t) &= \mathbf{C} h(t) + \mathbf{D} x(t)
\end{aligned}
$$
To integrate this mechanism into discrete deep neural networks, continuous parameters $(\mathbf{A}, \mathbf{B})$ are transformed into discrete parameters $(\mathbf{\bar{A}}, \mathbf{\bar{B}})$ using zero-order hold (ZOH) discretization with a learned timescale parameter $\Delta$:
$$
\begin{aligned}
\mathbf{\bar{A}} &= \exp(\Delta \mathbf{A})
\mathbf{\bar{B}} &= (\Delta \mathbf{A})^{-1} (\exp(\Delta \mathbf{A}) - \mathbf{I}) \cdot \Delta \mathbf{B} \approx \Delta \mathbf{B}
\end{aligned}
$$
Unlike classical linear time-invariant (LTI) systems where $\mathbf{A}, \mathbf{B}, \mathbf{C}$ remain constant across tokens, Mamba introduces input-dependent selection mechanisms that parameterize transition matrices dynamically:
$$
\begin{aligned}
h_t &= \mathbf{\bar{A}}t h{t-1} + \mathbf{\bar{B}}_t x_t
y_t &= \mathbf{C}_t h_t + \mathbf{D} x_t
\end{aligned}
$$
Where:
- $x_t \in \mathbb{R}^d$ is the input token projection at step $t$.
- $h_t \in \mathbb{R}^{d \times n}$ is the internal hidden state matrix ($n$ represents the state expansion dimension, set to 16 in Jamba).
- $\Delta_t, \mathbf{B}_t, \mathbf{C}_t$ are input-dependent functions computed via linear projections of $x_t$.
- $\mathbf{D}$ represents a parameterized skip connection.
In standard sequential execution, computing $h_t$ iteratively would create an autoregressive recurrence bottleneck. Mamba resolves this via a hardware-aware parallel associative scan. By reformulating the recurrence as a prefix scan over discretized state transitions, Jamba 1.5 evaluates the entire prompt sequence in parallel across accelerator GPU SRAM, achieving training and prefill speeds comparable to or faster than causal FlashAttention.
Most importantly, during autoregressive generation, each Mamba layer retains only the state matrix $h_t \in \mathbb{R}^{d \times n}$. Its memory footprint is completely constant: it requires exactly the same amount of memory whether the sequence length is 5 tokens or 250,000 tokens.
Multi-Head Self-Attention: Periodic Anchor Layers
While Mamba excels at continuous token compression and local context synthesis, pure SSMs can struggle to retrieve isolated tokens buried deep within historical contexts. Jamba 1.5 resolves this by introducing standard multi-head self-attention once every 8 layers:
$$ \text{Attention}(Q, K, V) = \text{Softmax}\left(\frac{Q K^T}{\sqrt{d_k}} + M ight) V $$
Where $M$ is the causal autoregressive mask. Because attention layers appear infrequently, Jamba 1.5 can allocate larger head dimensions and apply Grouped-Query Attention (GQA) without exhausting GPU memory. These periodic attention layers act as associative anchors, querying historical tokens across the sequence and re-injecting precise factual representations into the Mamba state streams.
Sparse Mixture-of-Experts (MoE) Subsystem
Following both the Mamba and Attention blocks, Jamba 1.5 incorporates a sparse Mixture-of-Experts feed-forward network. Each MoE layer contains 16 distinct feed-forward neural networks (experts), with a learned gating router dispatching each token to the top-2 experts:
$$y_{\text{moe}} = \sum_{i \in \text{Top-2}(G(x))} G(x)_i \cdot E_i(x)$$
Where $G(x) = \text{Softmax}(\text{Top-2}(\text{Gate}(x)))$ computes routing probabilities, and $E_i(x) = \text{SwiGLU}(x, W_i^{\text{gate}}, W_i^{\text{up}}, W_i^{\text{down}})$ represents the $i$-th expert’s feed-forward transformation.
By activating only 2 of 16 experts per token, Jamba 1.5 dramatically decouples total parameter capacity from floating-point arithmetic costs:
+-----------------------------------------------------------------------------------------+
|                               JAMBA 1.5 MODEL SPECIFICATIONS                            |
+--------------------------+------------------------------+-------------------------------+
| Architectural Parameter  | Jamba 1.5 Mini               | Jamba 1.5 Large               |
+--------------------------+------------------------------+-------------------------------+
| Total Parameters         | 52 Billion                   | 398 Billion                   |
| Active Parameters / Tok  | 12 Billion                   | 94 Billion                    |
| Interleaving Ratio       | 7 Mamba : 1 Attention        | 7 Mamba : 1 Attention         |
| Total Layer Depth        | 32 Layers (4 Blocks of 8)    | 64 Layers (8 Blocks of 8)     |
| Total Attention Layers   | 4 Layers Total               | 8 Layers Total                |
| Total Mamba SSM Layers   | 28 Layers Total              | 56 Layers Total               |
| Hidden Dimension ($d$)   | 4,096                        | 8,192                         |
| Number of Experts        | 16 Experts (Top-2 Active)    | 16 Experts (Top-2 Active)     |
| Context Window Length    | 256,000 Tokens (256K)        | 256,000 Tokens (256K)         |
| Native Quantization      | ExpertsInt8 Supported        | ExpertsInt8 Supported         |
| Minimum Serving Hardware | 1x NVIDIA A100/H100 (80GB)   | 1x 8-GPU Node (8x 80GB HBM)   |
+--------------------------+------------------------------+-------------------------------+ Notice the structural significance: in Jamba 1.5 Large, across 64 total model layers, only 8 layers generate KV cache entries. An equivalent 70B or 405B dense Transformer maintains 64 to 128 layers of full KV cache. This structural economy is what unlocks scalable 256K context processing.
Serving Implementation: Deploying Jamba 1.5 with Native ExpertsInt8
Deploying Jamba 1.5 in enterprise production leverages HuggingFace Transformers, vLLM, and TensorRT-LLM frameworks with native support for hybrid Mamba-Attention operators and ExpertsInt8 quantization.
Understanding ExpertsInt8 Quantization
A major hurdle when serving Mixture-of-Experts models is physical memory residency. Although Jamba 1.5 Large activates only 94B parameters per token, the full 398B parameter ensemble must remain resident in GPU memory to prevent catastrophic latency penalties from host memory swapping.
To make Jamba 1.5 Large accessible on standard 8-GPU enterprise nodes (such as 8x 80GB NVIDIA A100 or H100 servers), AI21 Labs developed ExpertsInt8. In this scheme:
- The attention projections, Mamba state matrices, and MoE gating routers are preserved in full BF16 precision, safeguarding numerical stability and reasoning fidelity.
- The 16 expert feed-forward matrices ($W_{\text{gate}}, W_{\text{up}}, W_{\text{down}}$)—which account for over 85% of total model weights—are quantized to 8-bit integers (INT8).
Because experts are memory-bandwidth-bound during single-batch and low-concurrency generation, dequantizing INT8 weights on-the-fly inside tensor cores introduces zero latency overhead while reducing model memory footprint from ~800GB down to under 430GB.
Production Python Serving Architecture
The following complete Python service demonstrates how to initialize Jamba 1.5 Mini or Large using HuggingFace and vLLM with Mamba kernel acceleration, automated memory budgeting, and long-context processing:
"""
Production Serving Module for AI21 Jamba 1.5 Hybrid Models
Demonstrates vLLM integration, Mamba kernel configuration,
and 256K context generation.
"""

import os
import sys
import time
from typing import Dict, Any, List, Optional
import torch

# High-performance inference engine abstraction
try:
    from vllm import LLM, SamplingParams
    from vllm.model_executor.models.jamba import JambaForCausalLM
except ImportError:
    # Graceful fallback simulation for local testing and CI linting
    LLM = None
    SamplingParams = None

class Jamba15ServingEngine:
    """Production serving wrapper for AI21 Jamba 1.5 Mini and Large."""

    def __init__(
        self,
        model_name: str = "ai21labs/AI21-Jamba-1.5-Mini",
        max_model_len: int = 262144,  # Full 256K context window
        tensor_parallel_size: int = 1,
        gpu_memory_utilization: float = 0.90,
        enable_experts_int8: bool = True
    ):
        self.model_name = model_name
        self.max_model_len = max_model_len
        self.tp_size = tensor_parallel_size
        self.gpu_util = gpu_memory_utilization
        self.enable_int8 = enable_experts_int8
        self.engine = None
        self._initialize_serving_runtime()

    def _initialize_serving_runtime(self) -> None:
        """Configures vLLM runtime with optimized Mamba SSM kernels."""
        print(f"[Jamba-Init] Initializing Jamba 1.5 Engine: {self.model_name}")
        print(f"[Jamba-Init] Max Context Length: {self.max_model_len} tokens (256K)")
        print(f"[Jamba-Init] Tensor Parallelism: {self.tp_size} GPUs")
        print(f"[Jamba-Init] ExpertsInt8 Quantization: {self.enable_int8}")

        quantization_param = "experts_int8" if self.enable_int8 else None

        if LLM is not None:
            # Initialize production vLLM instance
            self.engine = LLM(
                model=self.model_name,
                tensor_parallel_size=self.tp_size,
                max_model_len=self.max_model_len,
                gpu_memory_utilization=self.gpu_util,
                quantization=quantization_param,
                trust_remote_code=True,
                enforce_eager=False  # Enable CUDA graph optimization
            )
            print("[Jamba-Init] vLLM engine initialized with native Mamba CUDA kernels.")
        else:
            print("[Jamba-Init] Simulating serving engine in development environment.")

    def calculate_kv_cache_savings(self, sequence_length: int, batch_size: int) -> Dict[str, float]:
        """
        Compares Jamba 1.5 KV cache memory footprint against an equivalent dense Transformer.
        Standard Transformer: 64 attention layers.
        Jamba 1.5: 8 attention layers (7:1 interleaving ratio).
        """
        head_dim = 128
        kv_heads = 8
        bytes_per_elem = 2  # FP16/BF16

        # KV cache per token per layer: 2 * kv_heads * head_dim * bytes_per_elem
        kv_bytes_per_token_layer = 2 * kv_heads * head_dim * bytes_per_elem

        transformer_total_bytes = 64 * kv_bytes_per_token_layer * sequence_length * batch_size
        jamba_total_bytes = 8 * kv_bytes_per_token_layer * sequence_length * batch_size

        transformer_gb = transformer_total_bytes / (1024 ** 3)
        jamba_gb = jamba_total_bytes / (1024 ** 3)
        reduction_factor = transformer_gb / max(jamba_gb, 1e-6)

        return {
            "sequence_length": sequence_length,
            "batch_size": batch_size,
            "transformer_kv_cache_gb": round(transformer_gb, 2),
            "jamba_kv_cache_gb": round(jamba_gb, 2),
            "memory_saved_gb": round(transformer_gb - jamba_gb, 2),
            "reduction_factor": round(reduction_factor, 1)
        }

    def generate(
        self,
        prompts: List[str],
        max_tokens: int = 512,
        temperature: float = 0.7,
        top_p: float = 0.9
    ) -> List[Dict[str, Any]]:
        """Executes high-throughput text generation across long-context batches."""
        start_time = time.time()
        results = []

        if self.engine is not None and SamplingParams is not None:
            sampling_params = SamplingParams(
                max_tokens=max_tokens,
                temperature=temperature,
                top_p=top_p
            )
            outputs = self.engine.generate(prompts, sampling_params)
            for output in outputs:
                results.append({
                    "prompt": output.prompt,
                    "generated_text": output.outputs[0].text,
                    "tokens_generated": len(output.outputs[0].token_ids),
                    "finish_reason": output.outputs[0].finish_reason
                })
        else:
            # Simulated benchmark execution
            for idx, p in enumerate(prompts):
                results.append({
                    "prompt": p[:80] + "...",
                    "generated_text": f"Simulated Jamba 1.5 output response for batch item {idx}.",
                    "tokens_generated": max_tokens,
                    "finish_reason": "length"
                })

        duration = round(time.time() - start_time, 3)
        print(f"[Jamba-Exec] Generated {len(prompts)} sequences in {duration}s.")
        return results

# Example Execution
if __name__ == "__main__":
    serving = Jamba15ServingEngine(
        model_name="ai21labs/AI21-Jamba-1.5-Mini",
        max_model_len=262144,
        tensor_parallel_size=1,
        enable_experts_int8=True
    )

    # Calculate memory savings on a massive 200,000 token document
    savings = serving.calculate_kv_cache_savings(sequence_length=200000, batch_size=4)
    print("
[KV Cache Memory Analysis on 200k Context (Batch Size = 4)]")
    print(f"  - Dense Transformer KV Cache: {savings['transformer_kv_cache_gb']} GB")
    print(f"  - Jamba 1.5 Hybrid KV Cache:  {savings['jamba_kv_cache_gb']} GB")
    print(f"  - Physical Memory Saved:      {savings['memory_saved_gb']} GB")
    print(f"  - Compression Advantage:      {savings['reduction_factor']}x lower footprint")

    # Run test generation
    sample_queries = [
        "Analyze the following multi-chapter quarterly SEC filing and extract risk factors: [200k context tokens...]",
        "Synthesize cross-repository API changes and identify breaking interface contracts: [150k context tokens...]"
    ]
    outputs = serving.generate(sample_queries, max_tokens=128)
    print(f"
[Generation Complete] Processed {len(outputs)} production requests.") The script demonstrates how Jamba 1.5 translates mathematical elegance into practical engineering savings. On an enterprise workload with 200,000 input tokens across a concurrency of 4, a standard Transformer demands over 100 gigabytes of KV cache memory. Jamba 1.5 slashes this requirement to approximately 13 gigabytes, allowing high-concurrency long-context serving on standard off-the-shelf GPU infrastructure. For engineering teams evaluating model deployments, review complete operational integration workflows in our AIFetchly Developer Documentation.
Performance Benchmarks: Long-Context Throughput and Memory Scaling
Comprehensive benchmarks evaluate Jamba 1.5 against frontier open-weight models—including Meta’s Llama 3.1 70B, Llama 3.1 8B, and Mixtral 8x22B—across context scaling, generation throughput, and retrieval fidelity.
Benchmark 1: RULER Long-Context Retrieval Accuracy
The RULER benchmark evaluates models across complex multi-task long-sequence scenarios, including multi-hop variable tracing, synthetic aggregation, and needle-in-a-haystack retrieval:
RULER Benchmark Score Across Context Lengths (Higher is Better)
========================================================================================
Model Architecture      | 32K Context | 64K Context | 128K Context | 256K Context
------------------------+-------------+-------------+--------------+--------------------
Llama 3.1 8B Instruct   | 92.4%       | 88.1%       | 74.2%        | Degradation (N/A)
Llama 3.1 70B Instruct  | 95.8%       | 94.2%       | 87.5%        | Degradation (N/A)
Mixtral 8x22B Instruct  | 91.0%       | 84.5%       | Degradation  | Degradation (N/A)
Jamba 1.5 Mini (12B/52B)| 94.6%       | 93.8%       | 91.2%        | 88.4% (Effective)
Jamba 1.5 Large (94B/398)| 96.7%      | 96.1%       | 94.8%        | 93.2% (Effective)
======================================================================================== While standard dense Transformers exhibit steep retrieval degradation as sequence lengths exceed 64K and 128K tokens, Jamba 1.5 maintains high retrieval fidelity all the way to 256K tokens. The periodic attention layers provide reliable associative anchor points, preventing the state saturation that impairs pure SSMs.
In detailed depth evaluations—where targeted information is embedded at 10%, 50%, and 90% sequence depth—Jamba 1.5 maintains over 98% accuracy across all positions. The combination of Mamba’s continuous recurrence and periodic cross-attention ensures that information placed at the very beginning of a 256K window remains just as accessible as information at the end.
Benchmark 2: Inference Throughput Under Extended Contexts
As context length scales, the quadratic prefill and KV cache loading penalties of pure Transformers severely throttle token generation throughput:
Inference Generation Throughput (Tokens/Second/GPU) - Higher is Better
-----------------------------------------------------------------------------
At 8K Context Length:
  Llama 3.1 70B (8x H100)       | [==============================] 48 tok/s
  Jamba 1.5 Large (8x H100 INT8)| [==================================>] 54 tok/s

At 64K Context Length:
  Llama 3.1 70B (8x H100)       | [====================>] 32 tok/s
  Jamba 1.5 Large (8x H100 INT8)| [========================================>] 62 tok/s

At 128K Context Length:
  Llama 3.1 70B (8x H100)       | [=============>] 19 tok/s
  Jamba 1.5 Large (8x H100 INT8)| [====================================>] 51 tok/s

At 256K Context Length:
  Llama 3.1 70B (8x H100)       | [===>] OOM / 6 tok/s (Heavy offloading)
  Jamba 1.5 Large (8x H100 INT8)| [==============================] 42 tok/s (2.5x Faster)
----------------------------------------------------------------------------- At 256K context lengths, Jamba 1.5 Large achieves over 2.5x the generation throughput of Llama 3.1 70B. The speedup stems directly from hardware memory bandwidth dynamics: because Jamba’s KV cache is up to ten times smaller, memory controllers spend significantly less time streaming historical activation caches into arithmetic registers. This enables high-concurrency production deployments where multiple 256K streams run concurrently without saturating memory channels.
Benchmark 3: Hardware Footprint and Serving Economics
The table below contrasts the physical hardware footprint and operational expenditure required to serve 256K context workloads:
| Operational Metric | Llama 3.1 70B (Dense Transformer) | Jamba 1.5 Large (Hybrid MoE) | Jamba 1.5 Mini (Hybrid MoE) |
|---|---|---|---|
| Minimum Serving Hardware | 16x NVIDIA H100 (2 Nodes) | 8x NVIDIA H100 (1 Node) | 1x NVIDIA H100 (1 GPU) |
| KV Cache Size per 256K Stream | ~32 GB | ~3.2 GB (10x Smaller) | ~1.6 GB |
| Max Concurrent 256K Streams | 2 Streams / Node | 18 Streams / Node | 32 Streams / Node |
| Native Quantization Scheme | FP8 / INT4 (Post-Training) | ExpertsInt8 (Native) | ExpertsInt8 (Native) |
| Serving Cost per 1M Tokens (256K) | ~$1.80 | ~$0.45 (75% Cheaper) | ~$0.12 (93% Cheaper) |
By consolidating long-context serving into a single 8-GPU chassis and multiplying concurrent stream capacity by up to nine times, Jamba 1.5 fundamentally transforms the unit economics of enterprise AI. Infrastructure leaders can explore comparative infrastructure cost projections in our Enterprise Model Serving Pricing Guide.
Production Engineering: Deployment Patterns, Telemetry, and Best Practices
Deploying hybrid SSM-Transformer architectures into enterprise cloud environments requires specific orchestration strategies to maximize throughput and hardware utilization.
Kubernetes Production Manifest with Triton / vLLM
Below is a production-grade Kubernetes manifest configuring Jamba 1.5 Large on an 8-GPU NVIDIA H100 node using the vLLM orchestration engine:
apiVersion: apps/v1
kind: Deployment
metadata:
  name: jamba-15-large-serving
  namespace: ai-inference
  labels:
    app.kubernetes.io/name: jamba-large-engine
spec:
  replicas: 2
  selector:
    matchLabels:
      app.kubernetes.io/name: jamba-large-engine
  template:
    metadata:
      labels:
        app.kubernetes.io/name: jamba-large-engine
    spec:
      containers:
        - name: vllm-jamba-container
          image: vllm/vllm-openai:v0.6.0
          args:
            - '--model=ai21labs/AI21-Jamba-1.5-Large'
            - '--tensor-parallel-size=8'
            - '--max-model-len=262144'
            - '--quantization=experts_int8'
            - '--gpu-memory-utilization=0.92'
            - '--enable-chunked-prefill=true'
            - '--max-num-batched-tokens=16384'
          resources:
            limits:
              nvidia.com/gpu: '8'
              memory: '650Gi'
              cpu: '64'
            requests:
              nvidia.com/gpu: '8'
              memory: '450Gi'
              cpu: '32'
          ports:
            - containerPort: 8000
              name: openai-api
            - containerPort: 9090
              name: prometheus
          readinessProbe:
            httpGet:
              path: /health
              port: 8000
            initialDelaySeconds: 120
            periodSeconds: 15
          livenessProbe:
            httpGet:
              path: /health
              port: 8000
            initialDelaySeconds: 180
            periodSeconds: 30
          volumeMounts:
            - name: dshm
              mountPath: /dev/shm
      volumes:
        - name: dshm
          emptyDir:
            medium: Memory
sizeLimit: 64Gi Essential Production Best Practices for Jamba 1.5
- Activate Chunked Prefills for Extended Contexts: When ingesting 100k+ token prompts, standard continuous prefill can cause transient latency spikes for concurrent decoding requests. Enabling chunked prefills (
--enable-chunked-prefill=true) slices massive prompts into discrete 8k/16k token chunks, ensuring smooth inter-token latency across concurrent streams. - Standardize on FlashAttention-3 and Mamba-2 CUDA Kernels: Ensure your container environment includes compiled Triton and CUDA scan kernels optimized for your GPU generation. FlashAttention-3 accelerates periodic attention anchors, while optimized associative scan kernels maximize Mamba SSM throughput.
- Monitor MoE Expert Load Balancing: Instrument Prometheus metrics to track token distribution across the 16 experts. While Jamba 1.5 uses auxiliary-loss-free routing mechanisms, uneven domain inputs (such as pure code or mathematical proofs) can concentrate load onto specific expert pairs. Setting up alert rules on routing skew ensures consistent latency.
- Integrate Real-Time Document Fetching Pipelines: Because Jamba 1.5 can ingest entire libraries of documentation in a single prompt, pairing the model with low-latency distributed data fetching pipelines ensures that external context is fed continuously without I/O starvation.
- Decouple Ingestion from Autoregressive Serving via gRPC: To fully capture Jamba’s high throughput, connect upstream web scraping and document ingestion agents using high-concurrency streaming gRPC integrations rather than standard synchronous HTTP connections.
- Tune Continuous Batching Parameters: In vLLM, configure max batch sizes dynamically based on input sequence distributions. Because Jamba’s KV cache is 10x smaller, operators can safely configure higher
max-num-seqsvalues without risking memory thrashing or out-of-memory worker crashes.
The Horizon for Hybrid AI Systems
The release of AI21 Jamba 1.5 validates a crucial paradigm shift in foundation model engineering: the future of artificial intelligence does not belong to pure Transformers or pure State Space Models, but to principled architectural hybrids.
By mathematically uniting the selective compression of Mamba, the associative anchor precision of self-attention, and the sparse parameter scaling of Mixture-of-Experts, Jamba 1.5 establishes an unbeatable efficiency standard for enterprise context processing. Delivering verified 256K context retrieval, a 10x smaller KV cache footprint, and single-node hardware consolidation, Jamba 1.5 provides the ideal operational foundation for the next generation of autonomous reasoning systems. To explore how your organization can deploy hybrid architectures into automated production workflows, explore the AIFetchly Enterprise Solutions Portal.