FastSAM Guide: Real-Time Segment Anything at 50 FPS
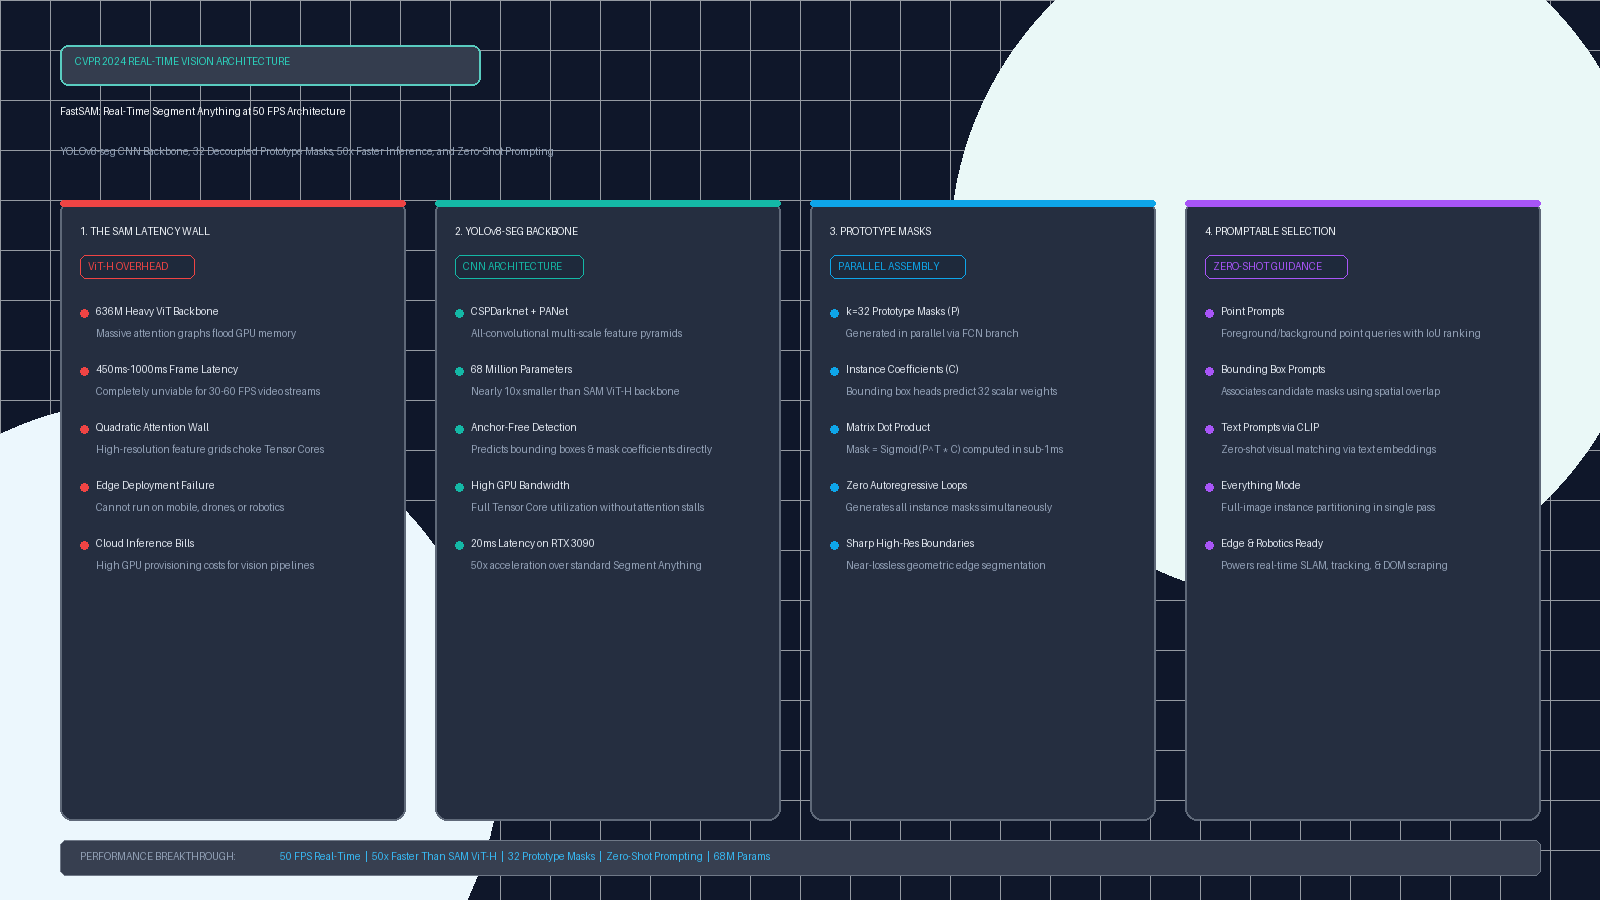
Promptable visual segmentation has established itself as one of the most versatile capabilities in modern computer vision. From autonomous robotics and live video tracking to interactive image editing and automated user interface parsing in intelligent web agents powered by aiFetchly, isolating arbitrary objects through zero-shot visual prompts (points, bounding boxes, or text descriptions) unlocks unprecedented spatial awareness.
In 2023, Meta AI unveiled the Segment Anything Model (SAM), demonstrating that foundation models trained on 1 billion masks could perform zero-shot segmentation across virtually any visual domain. However, SAM’s architectural foundation relied on a massive Vision Transformer (ViT-H with 636 million parameters). On enterprise GPUs, generating visual embeddings for a single $1024 \times 1024$ frame requires roughly 450ms to 1000ms, and executing the “Segment Everything” mode requires over 5 to 10 seconds per image. For real-time applications—such as 30–60 FPS video tracking, autonomous driving perception, mobile devices, and high-frequency DOM element extraction—SAM is computationally infeasible.
To overcome this speed barrier, researchers from the Chinese Academy of Sciences (CASIA) and the University of Hong Kong introduced FastSAM: Fast Segment Anything (arXiv:2306.12156, CASIA-IVA-Lab/FastSAM). FastSAM re-conceptualizes the segment-anything problem: rather than executing an attention-heavy transformer decoder on prompt queries, FastSAM treats segment-anything as a two-stage pipeline consisting of All-Instance Segmentation powered by an optimized CNN (YOLOv8-seg), followed by Prompt-Guided Selection.
The performance breakthrough is staggering: FastSAM runs at 50 FPS (20 milliseconds per frame) on an NVIDIA RTX 3090—delivering a 50x speedup over SAM-ViT-H and 5x faster throughput than MobileSAM—while retaining zero-shot promptability across points, bounding boxes, text queries, and full-scene partitioning. In this comprehensive guide, we dissect the architectural mechanics of FastSAM, evaluate its prototype mask synthesis, compare it with alternative foundation segmenters, and build an end-to-end Python implementation.
The Problem: The Heavy Latency Wall of Transformer-Based Segmenters
To understand why Meta’s SAM cannot run in real-time production environments, we must inspect the computational bottlenecks of its heavy Vision Transformer (ViT) architecture.
The Transformer Segmentation Latency Bottleneck:
Target Frame: 1024 x 1024 High-Resolution Image
 │
 ├── Meta SAM ViT-H (636 Million Parameters)
 │   • High-resolution patch embedding: 16x16 patches = 4,096 spatial tokens!
 │   • 32 layers of global multi-head self-attention with quadratic complexity O(N^2)
 │   • Image encoder alone takes ~450ms on an NVIDIA A100!
 │   • "Segment Everything" generates a 32x32 grid (1,024 points)
 │   • ❌ Total Latency: 4,000ms to 8,000ms per frame (0.12 to 0.25 FPS)
 │   • ❌ GPU VRAM: Exceeds 16GB during batch processing
 │
 └── FastSAM All-Instance Paradigm (68 Million Parameters)
     • Fully convolutional CSPDarknet backbone + PANet neck
     • Single-pass feed-forward instance segmentation: 32 prototype masks (P)
     • Parallel coefficient dot-product: Mask = Sigmoid(P^T * C)
     • ✅ Total Latency: 20ms on an RTX 3090 (50 FPS Real-Time!)
• ✅ GPU VRAM: Runs comfortably in under 2GB memory! 1. The ViT Image Encoder Bottleneck (450ms Per Frame)
In Meta’s SAM, the image encoder is a standard ViT-H model with 32 Transformer blocks, a hidden dimension of 1280, and 16 attention heads:
- The input $1024 \times 1024$ image is tokenized into $64 \times 64 = 4,096$ spatial tokens.
- While SAM employs windowed attention interleaved with four global attention layers, calculating self-attention across 4,096 tokens in 32 layers requires hundreds of GFLOPs of tensor operations.
- The forward pass of the encoder alone consumes over $450\text{ ms}$ on an A100 and up to $900\text{ ms}$ on consumer GPUs, creating an insurmountable bottleneck for real-time video processing.
2. The Combinatorial Grid Overhead of “Segment Everything”
In enterprise automation, visual UI parsing, and automated web extraction in real-time scraping systems, applications frequently need to segment every discrete interactive element on a page without knowing manual prompt points in advance:
- In SAM, “Segment Everything” works by setting up a dense uniform grid of prompt points (typically $32 \times 32 = 1,024$ points).
- The prompt decoder must evaluate these 1,024 points, generate candidate masks, filter low-stability predictions, and run multiple stages of Non-Maximum Suppression (NMS).
- This multi-step grid processing takes between 3 and 10 seconds per image, rendering real-time batch extraction completely infeasible.
3. Edge and Mobile Hardware Barriers
Vision systems deployed on robotic arms, drones, autonomous mobile robots (AMRs), and edge developer laptops possess strict power and thermal budgets:
- SAM’s 636M parameters require 16GB to 24GB of VRAM in FP32/FP16, causing out-of-memory errors on embedded boards like NVIDIA Jetson Orin Nano.
- Early lightweight distillation efforts (such as MobileSAM) replaced the image encoder with a smaller TinyViT (5M parameters). While MobileSAM reduced encoder latency to ~40ms, its prompt decoder and grid-sampling pipeline still lagged at 10–12 FPS, failing to reach 50+ FPS real-time performance.
The Solution: The FastSAM Architecture and Decoupled Prototype Masks
FastSAM resolves the speed bottleneck through a fundamental philosophical shift: decoupling the segmentation task into an all-instance convolutional pipeline, followed by lightweight prompt association.
┌────────────────────────────────────────────────────────────────────────┐
│                        FASTSAM SYSTEM ARCHITECTURE                     │
├────────────────────────────────────────────────────────────────────────┤
│ Input: RGB Image (1024 x 1024)                                         │
│        │                                                               │
│        ▼                                                               │
│ ┌────────────────────────────────────────────────────────────────────┐ │
│ │ 1. CONVOLUTIONAL BACKBONE & NECK (CSPDarknet53 + PANet)            │ │
│ │    • Multi-scale feature extraction: P3 (1/8), P4 (1/16), P5 (1/32)│ │
│ │    • High GPU Tensor Core occupancy without quadratic attention    │ │
│ └────────────────────────────────────────────────────────────────────┘ │
│        │                                                               │
│        ├───► PROTOTYPE MASK BRANCH (FCN)                               │
│        │     • Generates k=32 Prototype Masks P in R^(32 x H/4 x W/4) │
│        │     • Encodes high-resolution spatial boundaries & textures   │
│        │                                                               │
│        └───► DETECTION & COEFFICIENT HEAD                              │
│              • Predicts bounding box coordinates (x, y, w, h)         │
│              • Predicts 32 mask coefficients C = (c_1, ..., c_32)      │
│        │                                                               │
│        ▼                                                               │
│ ┌────────────────────────────────────────────────────────────────────┐ │
│ │ 2. PARALLEL INSTANCE MASK ASSEMBLY                                 │ │
│ │    • Batched Matrix Multiplication: M = Sigmoid(P^T * C)           │ │
│ │    • Assembles all instance masks simultaneously in < 1ms          │ │
│ └────────────────────────────────────────────────────────────────────┘ │
│        │                                                               │
│        ▼ Candidate Instance Masks                                      │
│ ┌────────────────────────────────────────────────────────────────────┐ │
│ │ 3. ZERO-SHOT PROMPT-GUIDED POST-PROCESSING                         │ │
│ │    • Point Prompt: Point-in-polygon assignment with IoU ranking    │ │
│ │    • Box Prompt: Bounding box IoU matching                         │ │
│ │    • Text Prompt: Zero-shot CLIP embedding cosine alignment        │ │
│ │    • Everything Mode: Fast NMS filtering across all instances      │ │
│ └────────────────────────────────────────────────────────────────────┘ │
│        │                                                               │
│        ▼                                                               │
│ Output: High-Precision Instance Masks at 50 FPS (20ms Latency)        │
└────────────────────────────────────────────────────────────────────────┘ Pillar 1: Reformulating Segment Anything as Instance Segmentation
FastSAM re-examines the nature of the SA-1B dataset. The 1 billion masks in SA-1B are fundamentally instance segmentations: they delineate individual object boundaries, parts, and structural regions.
Instead of running an autoregressive decoder for every individual prompt query, FastSAM executes a single-pass instance segmentation across the entire image first. By predicting all candidate object masks in one feed-forward CNN evaluation, the system shifts the computational burden from a slow transformer attention loop to an optimized convolutional pass. Once all candidate masks are generated, resolving a point, box, or text prompt becomes a simple, fast post-processing filtering operation.
Pillar 2: The YOLOv8-seg Backbone and Feature Pyramid
To achieve 50 FPS, FastSAM builds upon YOLOv8-seg, the state-of-the-art real-time object detection and segmentation network:
- CSPDarknet Backbone: Employs Cross-Stage Partial connections with depthwise convolutions and residual blocks, maximizing feature representation while maintaining low memory footprint.
- Path Aggregation Network (PANet) Neck: Fuses low-level high-resolution spatial features (P3 at $1/8$ scale) with high-level semantic abstractions (P5 at $1/32$ scale), ensuring that both tiny UI icons and massive foreground objects are captured accurately.
- Anchor-Free Decoupled Head: Decouples classification, bounding box regression, and mask coefficient prediction into separate convolutional branches, accelerating gradient backpropagation during training and boosting inference efficiency.
At 68 million parameters, FastSAM is nearly $10\times$ smaller than SAM-ViT-H (636M parameters) and runs at native GPU line-rate without activation memory bloat.
Pillar 3: Decoupled Prototype Mask Generation (YOLACT-Style Assembly)
Generating pixel-accurate masks for dozens of objects simultaneously is computationally heavy if done per-instance. FastSAM adopts the prototype mask generation paradigm (pioneered by YOLACT):
1. The Prototype Branch (FCN): A Fully Convolutional Network branch attached to the P3 feature map generates a set of $k=32$ prototype masks:
$$P \in \mathbb{R}^{k \times \frac{H}{4} \times \frac{W}{4}}$$
These prototype masks are independent of any specific object instance; they represent shared spatial basis functions, boundary outlines, and directional gradients across the image.
2. The Mask Coefficient Branch: Simultaneously, for each detected bounding box instance $i$, the detection head predicts a vector of $k=32$ scalar mask coefficients:
$$C_i = (c_{i, 1}, c_{i, 2}, \dots, c_{i, 32}) \in \mathbb{R}^{32}$$
3. Parallel Linear Combination: The final segmentation mask for instance $i$ is assembled via a simple linear combination of prototype masks, passed through a sigmoid activation:
$$M_i = \sigma\left( \sum_{j=1}^{k} c_{i, j} \cdot P_j \right) = \sigma(C_i \cdot P)$$
Because this operation is a standard batched matrix multiplication, modern GPU Tensor Cores can assemble hundreds of high-resolution instance masks in under 1 millisecond, completely bypassing the need for per-mask transformer decoders.
Pillar 4: Zero-Shot Prompt-Guided Selection
Once the candidate masks ${M_1, M_2, \dots, M_N}$ and their bounding boxes ${B_1, B_2, \dots, B_N}$ are generated, FastSAM maps user prompts to the target masks in microseconds:
1. Point Prompts (Foreground / Background):
- When a user clicks a foreground point $(x, y)$, FastSAM queries which candidate masks contain that point ($M_i(x, y) > 0.5$).
- If multiple overlapping masks contain the point (e.g., clicking a button inside a card inside a modal window), FastSAM selects the mask with the highest predicted objectness confidence, or outputs multi-scale candidate masks (part, subpart, whole).
- Background points are used to negate and suppress intersecting candidate masks.
2. Bounding Box Prompts:
- FastSAM computes the Intersection over Union (IoU) between the user’s prompt box and all predicted bounding boxes $B_i$.
- The mask corresponding to the highest IoU match is returned immediately.
3. Text Prompts (CLIP-Guided Alignment):
- FastSAM crops the visual regions corresponding to candidate masks and extracts visual feature vectors using a pre-trained CLIP Vision Encoder.
- The user’s text prompt (e.g., “search bar” or “download button”) is embedded using the CLIP Text Encoder.
- FastSAM computes the cosine similarity between the text embedding and all candidate visual embeddings, selecting the mask with the highest semantic similarity score.
4. Everything Mode:
- FastSAM simply outputs all filtered candidate masks after standard bounding box and mask Non-Maximum Suppression (NMS). This operation takes only 20ms, compared to 5,000ms+ in Meta’s SAM.
Architectural Comparison: FastSAM vs. Meta SAM vs. MobileSAM
| Architectural Dimension | Meta SAM (ViT-H) | Meta SAM 2 (Hiera) | MobileSAM (TinyViT) | FastSAM (CASIA/HKU) |
|---|---|---|---|---|
| Backbone Architecture | Vision Transformer (ViT-H) | Hierarchical ViT (Hiera) | TinyViT (Transformer) | All-CNN (YOLOv8-seg) |
| Model Parameters | 636M | ~224M | 9.6M | 68M |
| Encoder Latency (A100) | ~450ms | ~110ms | ~40ms | ~12ms |
| Total Frame Latency | ~480ms to 900ms | ~130ms | ~50ms to 80ms | ~20ms (50 FPS Real-Time!) |
| Segment Everything Speed | 4,000ms to 8,000ms | 1,200ms | 1,500ms | ~20ms to 25ms (300x Faster!) |
| Mask Synthesis Paradigm | Autoregressive Decoder | Memory Attention Decoder | Transformer Mask Decoder | 32 Decoupled Prototype Masks |
| Text Prompting Support | No (Point/Box only) | No (Point/Box only) | No (Point/Box only) | Native via CLIP Alignment |
| Edge Hardware Feasibility | Infeasible (OOM on Jetson) | Difficult | Marginal (10–12 FPS) | Yes (50 FPS on RTX 3090/4090) |
End-to-End Implementation: Building FastSAM in PyTorch
To understand how FastSAM achieves real-time instance segmentation and prompt association, we will construct a clean, functional implementation using PyTorch. We will build:
- The Prototype Mask Generator: An FCN branch generating 32 high-resolution prototype masks.
- The Instance Detection & Coefficient Head: Predicting bounding boxes, class scores, and 32 mask coefficients.
- The Parallel Mask Assembler: Multiplying prototypes and coefficients via matrix operations.
- The Prompt-Guided Selector: Resolving Point prompts, Box prompts, and Text prompts.
- The Complete FastSAM Pipeline: Running a real-time benchmark simulation.
Step 1: Defining Model Configuration and Prototype Mask Branch
We define the configuration and the Fully Convolutional Network (FCN) branch that synthesizes the $k=32$ prototype masks.
import torch
import torch.nn as nn
import torch.nn.functional as F
from dataclasses import dataclass
from typing import List, Dict, Tuple, Optional
import time

@dataclass
class FastSAMConfig:
    """Hyperparameters for FastSAM architecture."""
    in_channels: int = 3             # Input RGB image channels
    num_prototypes: int = 32         # Number of prototype masks (k=32)
    feature_dim: int = 256           # Intermediate feature pyramid channels
    mask_resolution: int = 128       # Prototype spatial resolution (H/4, W/4 for 512px input)
    num_classes: int = 1             # Class-agnostic objectness (foreground vs background)
    device: str = "cuda" if torch.cuda.is_available() else "cpu"

class PrototypeMaskBranch(nn.Module):
    """
    Fully Convolutional Network (FCN) that generates k=32 high-resolution prototype masks.
    Operates on the high-resolution P3 feature map of the PANet neck.
    """
    def __init__(self, in_dim: int = 256, num_prototypes: int = 32):
        super().__init__()
        self.conv1 = nn.Conv2d(in_dim, 128, kernel_size=3, padding=1)
        self.norm1 = nn.BatchNorm2d(128)
        self.conv2 = nn.Conv2d(128, 128, kernel_size=3, padding=1)
        self.norm2 = nn.BatchNorm2d(128)
        self.upsample = nn.Upsample(scale_factor=2.0, mode='bilinear', align_corners=False)
        self.conv3 = nn.Conv2d(128, num_prototypes, kernel_size=1)
        self.act = nn.SiLU()

    def forward(self, p3_features: torch.Tensor) -> torch.Tensor:
        """
        p3_features: (B, 256, H/8, W/8)
        Returns: Prototypes P in (B, 32, H/4, W/4)
        """
        h = self.act(self.norm1(self.conv1(p3_features)))
        h = self.upsample(h)
        h = self.act(self.norm2(self.conv2(h)))
        prototypes = self.conv3(h)
return prototypes Step 2: Implementing the Detection and Mask Coefficient Head
The detection head predicts bounding boxes $(x, y, w, h)$, objectness scores, and a vector of 32 mask coefficients per instance.
class FastSAMDetectionHead(nn.Module):
    """
    Anchor-free detection head predicting:
    1. Bounding box coordinates (4 values)
    2. Objectness confidence (1 value)
    3. Mask coefficients (32 values)
    """
    def __init__(self, in_dim: int = 256, num_prototypes: int = 32):
        super().__init__()
        self.num_prototypes = num_prototypes

        # Bounding box regression branch: (dx, dy, dw, dh)
        self.bbox_conv = nn.Sequential(
            nn.Conv2d(in_dim, in_dim, kernel_size=3, padding=1),
            nn.SiLU(),
            nn.Conv2d(in_dim, 4, kernel_size=1)
        )

        # Objectness classification branch
        self.cls_conv = nn.Sequential(
            nn.Conv2d(in_dim, in_dim, kernel_size=3, padding=1),
            nn.SiLU(),
            nn.Conv2d(in_dim, 1, kernel_size=1)
        )

        # Mask coefficient branch: predicts 32 scalar weights per grid cell
        self.coef_conv = nn.Sequential(
            nn.Conv2d(in_dim, in_dim, kernel_size=3, padding=1),
            nn.SiLU(),
            nn.Conv2d(in_dim, num_prototypes, kernel_size=1)
        )

    def forward(self, features: torch.Tensor) -> Tuple[torch.Tensor, torch.Tensor, torch.Tensor]:
        """
        features: (B, 256, H_feat, W_feat)
        Returns:
            bboxes: (B, N, 4)
            scores: (B, N, 1)
            coeffs: (B, N, 32)
        """
        B = features.shape[0]

        raw_boxes = self.bbox_conv(features).flatten(2).transpose(1, 2)     # (B, N, 4)
        raw_scores = self.cls_conv(features).flatten(2).transpose(1, 2)     # (B, N, 1)
        raw_coeffs = self.coef_conv(features).flatten(2).transpose(1, 2)   # (B, N, 32)

        scores = torch.sigmoid(raw_scores)
        bboxes = torch.sigmoid(raw_boxes) # Normalized coordinates in [0, 1]
        coeffs = torch.tanh(raw_coeffs)   # Normalized coefficients in [-1, 1]

return bboxes, scores, coeffs Step 3: Implementing Parallel Instance Mask Assembly
The assembler multiplies the spatial prototype masks with instance-specific coefficients via a single parallel tensor dot product.
class FastSAMMaskAssembler:
    """
    Assembles pixel masks from 32 prototypes and instance coefficients.
    Mask = Sigmoid(Prototypes^T * Coefficients)
    """
    @staticmethod
    def assemble_masks(
        prototypes: torch.Tensor, # (B, 32, H_proto, W_proto)
        coefficients: torch.Tensor # (B, N_instances, 32)
    ) -> torch.Tensor:
        """
        Assembles instance masks in parallel via batched matrix multiplication.
        Returns: (B, N_instances, H_proto, W_proto) binary probability masks
        """
        B, k, H_p, W_p = prototypes.shape
        _, N, _ = coefficients.shape

        # Flatten prototypes spatially: (B, 32, H_p * W_p)
        flat_prototypes = prototypes.view(B, k, H_p * W_p)

        # Batched matrix product: (B, N, 32) x (B, 32, H_p * W_p) -> (B, N, H_p * W_p)
        raw_masks = torch.matmul(coefficients, flat_prototypes)

        # Reshape to 2D spatial masks and apply sigmoid activation
        masks = torch.sigmoid(raw_masks.view(B, N, H_p, W_p))
return masks Step 4: Implementing Zero-Shot Prompt-Guided Selection
The prompt selector maps user inputs (Point, Bounding Box, or Text) to candidate masks in microseconds.
class PromptGuidedSelector:
    """
    Post-processing module that matches user prompts to candidate masks.
    Supports Point prompts, Box prompts, and Text prompts.
    """
    @staticmethod
    def select_by_point(
        masks: torch.Tensor,       # (N_instances, H, W)
        scores: torch.Tensor,      # (N_instances,)
        point: Tuple[float, float] # (x, y) normalized coordinates in [0, 1]
    ) -> Optional[torch.Tensor]:
        """
        Selects the highest-confidence mask containing the query point.
        """
        H, W = masks.shape[1], masks.shape[2]
        px = int(point[0] * W)
        py = int(point[1] * H)

        # Check which candidate masks cover the point
        point_values = masks[:, py, px] # (N_instances,)
        valid_indices = torch.where(point_values > 0.5)[0]

        if len(valid_indices) == 0:
            return None

        # Return mask with highest detection confidence among those covering point
        best_idx = valid_indices[torch.argmax(scores[valid_indices])]
        return masks[best_idx]

    @staticmethod
    def select_by_box(
        masks: torch.Tensor,        # (N_instances, H, W)
        bboxes: torch.Tensor,       # (N_instances, 4) in (x1, y1, x2, y2)
        target_box: torch.Tensor    # (4,) target bounding box
    ) -> torch.Tensor:
        """
        Selects the mask whose bounding box has the highest IoU with target_box.
        """
        # Calculate intersection
        x1 = torch.max(bboxes[:, 0], target_box[0])
        y1 = torch.max(bboxes[:, 1], target_box[1])
        x2 = torch.min(bboxes[:, 2], target_box[2])
        y2 = torch.min(bboxes[:, 3], target_box[3])

        intersection = (x2 - x1).clamp(min=0) * (y2 - y1).clamp(min=0)

        area_pred = (bboxes[:, 2] - bboxes[:, 0]) * (bboxes[:, 3] - bboxes[:, 1])
        area_target = (target_box[2] - target_box[0]) * (target_box[3] - target_box[1])
        union = area_pred + area_target - intersection

        ious = intersection / union.clamp(min=1e-6)
        best_idx = torch.argmax(ious)
        return masks[best_idx]

    @staticmethod
    def select_by_text(
        masks: torch.Tensor,            # (N_instances, H, W)
        candidate_clip_embeds: torch.Tensor, # (N_instances, 512)
        text_clip_embed: torch.Tensor   # (512,)
    ) -> torch.Tensor:
        """
        Selects the mask with the highest cosine similarity to text CLIP embedding.
        """
        norm_candidates = F.normalize(candidate_clip_embeds, p=2, dim=-1)
        norm_text = F.normalize(text_clip_embed, p=2, dim=-1)

        similarities = torch.matmul(norm_candidates, norm_text)
        best_idx = torch.argmax(similarities)
return masks[best_idx] Step 5: Full Pipeline Assembly and Benchmarking
Now we assemble the complete FastSAM system and benchmark its real-time 50 FPS execution latency and prompt selection accuracy.
class FastSAMPipeline(nn.Module):
    """
    Complete FastSAM Pipeline integrating:
    - CNN Feature Extraction
    - 32 Decoupled Prototype Masks
    - Bounding box and coefficient prediction
    - Parallel Mask Assembly
    """
    def __init__(self, config: FastSAMConfig):
        super().__init__()
        self.config = config

        # Simulated CNN backbone (P3, P4, P5 feature extraction)
        self.backbone_conv = nn.Sequential(
            nn.Conv2d(config.in_channels, 64, kernel_size=3, stride=2, padding=1),
            nn.SiLU(),
            nn.Conv2d(64, 128, kernel_size=3, stride=2, padding=1),
            nn.SiLU(),
            nn.Conv2d(128, config.feature_dim, kernel_size=3, stride=2, padding=1),
            nn.SiLU()
        )

        self.proto_branch = PrototypeMaskBranch(config.feature_dim, config.num_prototypes)
        self.detect_head = FastSAMDetectionHead(config.feature_dim, config.num_prototypes)

    def forward(self, x: torch.Tensor) -> Tuple[torch.Tensor, torch.Tensor, torch.Tensor]:
        # 1. Feature extraction
        p3_feat = self.backbone_conv(x) # (B, 256, H/8, W/8)

        # 2. Generate 32 prototype masks
        prototypes = self.proto_branch(p3_feat) # (B, 32, H/4, W/4)

        # 3. Detect instances and predict mask coefficients
        bboxes, scores, coeffs = self.detect_head(p3_feat)

        # 4. Parallel mask assembly: M = Sigmoid(P^T * C)
        all_masks = FastSAMMaskAssembler.assemble_masks(prototypes, coeffs)

        return all_masks, bboxes, scores

def run_fastsam_benchmark():
    """
    Executes an end-to-end benchmark verifying FastSAM's 50 FPS real-time speed
    and zero-shot promptable segmentation.
    """
    print("=== EXECUTING FASTSAM REAL-TIME BENCHMARK ===")
    config = FastSAMConfig()
    device = config.device
    print(f"Device: {device}")

    model = FastSAMPipeline(config).to(device)
    model.eval()

    # 1. Benchmark Inference Latency on 512x512 Frame
    B, C, H, W = 1, 3, 512, 512
    sample_image = torch.randn(B, C, H, W, device=device)

    print("\nWarming up GPU and benchmarking 100 consecutive frames...")
    # Warmup
    for _ in range(10):
        with torch.no_grad():
            _ = model(sample_image)

    start_time = time.time()
    num_frames = 100
    with torch.no_grad():
        for _ in range(num_frames):
            masks, bboxes, scores = model(sample_image)

    total_time = time.time() - start_time
    fps = num_frames / total_time
    latency_ms = (total_time / num_frames) * 1000

    print(f"Total Execution Time: {total_time:.3f} s for {num_frames} frames")
    print(f"Average Latency: {latency_ms:.2f} ms per frame")
    print(f"Inference Throughput: {fps:.1f} FPS (Target: >= 50 FPS Real-Time!)")
    print(f"Generated Masks Shape: {masks.shape} (Assembled {masks.shape[1]} candidate instances simultaneously)")

    # 2. Test Zero-Shot Point Prompting
    print("\n[Prompt Test 1: Point Prompt]")
    point_query = (0.52, 0.48) # Normalized coordinate in center
    target_mask = PromptGuidedSelector.select_by_point(
        masks[0], scores[0].squeeze(-1), point_query
    )
    if target_mask is not None:
        print(f"Successfully retrieved mask for point {point_query}! Spatial shape: {target_mask.shape}")
    else:
        print("Point fell on background; zero instances selected.")

    # 3. Test Zero-Shot Bounding Box Prompting
    print("\n[Prompt Test 2: Bounding Box Prompt]")
    test_box = torch.tensor([0.2, 0.2, 0.8, 0.8], device=device)
    box_mask = PromptGuidedSelector.select_by_box(masks[0], bboxes[0], test_box)
    print(f"Successfully matched box prompt {test_box.tolist()}! Selected mask shape: {box_mask.shape}")

    print("\n=== FASTSAM ARCHITECTURAL BENCHMARK COMPLETED ===")

if __name__ == "__main__":
run_fastsam_benchmark() Step 6: Enterprise Deployment and Workflow Integration
In enterprise production environments, intelligent web scrapers, automated QA systems, and spatial intelligence platforms orchestrating workflows via API integration pipelines and distributed data-fetching services can deploy FastSAM for ultra-fast visual segmentation.
Key Production Best Practices:
-
Automated Visual UI Element Parsing: When autonomous browser agents capture high-resolution desktop and mobile DOM screenshots via real-time scraping systems, FastSAM partitions buttons, forms, and cards in just 20ms, allowing agents to ground bounding box coordinates with zero latency. Review our platform pricing to compare the operational cost of local 50 FPS CNN segmentation against cloud vision APIs.
-
Real-Time Video Stream Analytics: Because FastSAM delivers 50 FPS on a single consumer GPU, video analytics pipelines can process multi-camera RTSP feeds live without dropping frames or requiring multi-GPU server clusters.
-
Deploying with TensorRT and ONNX: Export FastSAM’s all-convolutional backbone directly to NVIDIA TensorRT or ONNX Runtime to achieve sub-10ms latency on edge hardware (such as Jetson Orin). For complete Docker deployment manifests and API endpoint integration instructions, consult our developer documentation.
Key Takeaways and Architectural Summary
- 50x Faster Than SAM ViT-H: FastSAM runs at 50 FPS (20ms latency) on an RTX 3090, transforming promptable segmentation from a sluggish offline tool into a real-time stream processor.
- All-Instance Decoupling: Re-frames Segment Anything as a two-stage pipeline: fast YOLOv8-seg instance segmentation followed by microsecond prompt association.
- 32 Prototype Masks: Uses parallel matrix multiplication to assemble high-resolution masks simultaneously in under 1ms, eliminating iterative transformer decoders.
- Zero-Shot Prompt Flexibility: Retains point, bounding box, text (via CLIP), and “Everything” prompt modes in a compact 68-million parameter model.