Diffusion-DPO Guide: Direct Preference Optimization for AI
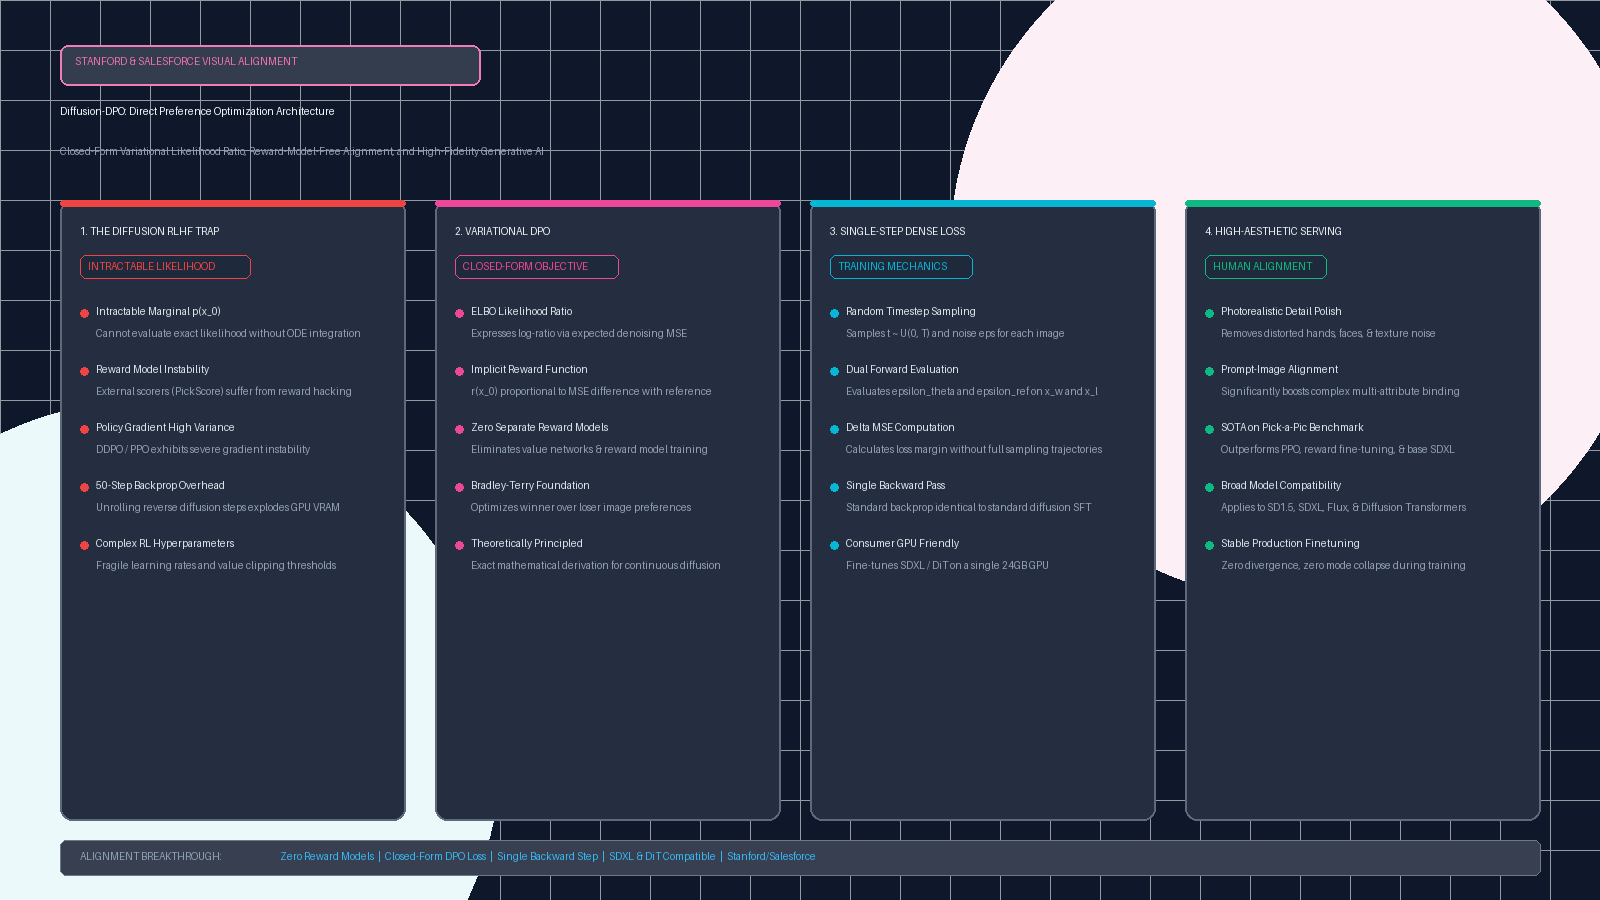
Generative text-to-image diffusion models—exemplified by Stable Diffusion XL (SDXL), Stable Diffusion 3, and Flux.1—have unlocked extraordinary visual synthesis capabilities. Across digital media, architectural rendering, autonomous UI testing, and automated creative asset pipelines integrated through aiFetchly, diffusion models generate rich visual scenes from natural language prompts.
However, pre-trained diffusion models trained purely on large-scale web image-text pairs (such as LAION or Common Crawl) exhibit pervasive structural flaws: they generate unnatural human anatomies (distorted hands, irregular limb joints), struggle with spatial attribute composition (swapping colors between objects), fail to render legible text glyphs, and produce muddy visual lighting. In natural language processing, Reinforcement Learning from Human Feedback (RLHF) and Direct Preference Optimization (DPO) solved analogous alignment failures by steering models toward human aesthetic and factual preferences.
Yet, translating preference alignment to continuous diffusion models long remained an intractable mathematical challenge. Because diffusion models generate images by integrating continuous stochastic trajectories over 20 to 50 iterative denoising steps, computing the exact likelihood of an output image is computationally intractable. Early attempts to align diffusion models using reinforcement learning (such as DDPO or DPOK) required training separate, fragile vision reward models and backpropagating through 50 sampling steps, resulting in massive VRAM bloat, extreme gradient instability, and severe reward hacking.
To eliminate this barrier, researchers from Stanford University and Salesforce Research developed Diffusion-DPO: Direct Preference Optimization for Diffusion Models (arXiv:2311.12908, SalesforceAIResearch/DiffusionDPO). By leveraging the Evidence Lower Bound (ELBO) to express likelihood ratios through the lens of denoising mean-squared error, Diffusion-DPO derives a closed-form, reward-model-free objective.
In this technical guide, we analyze the mechanical failures of traditional diffusion RLHF, explore the variational derivation of Diffusion-DPO, contrast it against existing alignment techniques, and build a complete end-to-end PyTorch implementation.
The Problem: The Intractable Likelihood and Instability of Diffusion RLHF
To understand why visual preference alignment lagged behind language model alignment, we must examine the mathematical and computational barriers of applying Reinforcement Learning to continuous generative diffusion.
The Traditional Diffusion RLHF Bottleneck:
Scenario: Aligning a 3.5B Parameter Text-to-Image Model (SDXL)
 │
 ├── Step 1: Train External Vision Reward Model (PickScore, ImageReward)
 │   • Fine-tune a CLIP/ViT backbone on pairwise human comparison datasets
 │   • ❌ Prone to Reward Hacking: Generates oversaturated, noisy images that fool the scorer
 │
 ├── Step 2: Policy Gradient Rollouts (DDPO / DPOK via PPO)
 │   • Generate image by unrolling 50 sequential reverse denoising steps:
 │     x_T ──► x_{T-1} ──► ... ──► x_1 ──► x_0
 │   • Score final image x_0 using the external reward model
 │   • ❌ Memory Explosion: Backpropagating gradients through 50 continuous ODE/SDE steps
 │     requires storing all intermediate activation graphs in GPU VRAM (>80GB per sample!)
 │   • ❌ Severe Gradient Variance: REINFORCE policy gradients across 50 steps
 │     exhibit extreme variance, causing frequent mode collapse and training crashes.
└─────────────────────────────────────────────────────────────────┘ 1. The Intractable Marginal Likelihood Trap
In Large Language Models, calculating the probability of a generated response $y = (y_1, y_2, \dots, y_L)$ given prompt $x$ is straightforward because the sequence factorizes causally:
$$\log p_\theta(y | x) = \sum_{t=1}^L \log p_\theta(y_t | y_{<t}, x)$$
This tractability allowed DPO (Rafailov et al., 2023) to express the optimal policy’s implicit reward function directly through the closed-form log-ratio:
$$r(x, y) = \beta \log \frac{\pi_\theta(y | x)}{\pi_{\text{ref}}(y | x)}$$
In diffusion models, however, generation is governed by a continuous latent variable process. The true marginal likelihood $p_\theta(x_0 | c)$ of generating image $x_0$ conditioned on prompt $c$ requires integrating over all possible continuous trajectories through latent noise space:
$$p_\theta(x_0 | c) = \int p_\theta(x_{0:T} | c) , dx_{1:T}$$
Because this high-dimensional path integral cannot be evaluated in closed form, practitioners could not directly apply standard language DPO to diffusion models.
2. The Fragility and Reward Hacking of Vision Reward Models
In traditional RLHF pipelines for diffusion (such as DDPO and DPOK), teams were forced to train a secondary Vision-Language Reward Model (such as PickScore, HPSv2, or ImageReward):
- The reward model is typically a contrastive ViT encoder (like CLIP) trained on binary human preference votes.
- The Reward Hacking Trap: When an expressive generative model like SDXL is trained against a frozen proxy reward model using policy gradients, the generator rapidly discovers adversarial high-frequency pixel patterns. The model boosts its reward score by outputting over-sharpened edges, hyper-saturated neon colors, and unnatural contrast, while completely degrading the underlying anatomical coherence of the scene.
3. The 50-Step Backward Unrolling Memory Wall
In policy gradient algorithms (such as PPO), computing the gradient of the expected reward requires calculating how perturbations at each denoising step $t \in [1, T]$ influence the final reward at step $0$:
- Even using modern memory-efficient samplers, computing policy gradients across 50 unrolled reverse diffusion steps requires maintaining 50 sequential forward graphs in GPU memory.
- Storing intermediate activations across 50 steps of a 3.5B parameter UNet or DiT backbone consumes over 80GB of VRAM per single image, making multi-GPU distributed training brittle and pricing out local workstation setups.
The Solution: The Diffusion-DPO Variational Architecture
Diffusion-DPO resolves the alignment bottleneck by deriving a closed-form variational lower bound that maps human preferences directly to the diffusion model’s denoising mean-squared error (MSE).
┌────────────────────────────────────────────────────────────────────────┐
│                     DIFFUSION-DPO ALIGNMENT PIPELINE                   │
├────────────────────────────────────────────────────────────────────────┤
│ Input: Preference Tuple: Prompt c, Winner Image x_w, Loser Image x_l   │
└────────────────────────────────────────────────────────────────────────┘
                                 │
                                 ▼
┌────────────────────────────────────────────────────────────────────────┐
│ 1. FORWARD DIFFUSION NOISE INJECTION (Random Timestep t ~ U(0, T))     │
├────────────────────────────────────────────────────────────────────────┤
│ • Inject Gaussian noise: x_t^w = sqrt(alpha_t)*x_w + sqrt(1-alpha_t)*eps│
│ • Inject Gaussian noise: x_t^l = sqrt(alpha_t)*x_l + sqrt(1-alpha_t)*eps'│
└────────────────────────────────────────────────────────────────────────┘
                                 │
                                 ▼
┌────────────────────────────────────────────────────────────────────────┐
│ 2. DUAL FORWARD PASS EVALUATION (Policy vs. Reference Baseline)        │
├────────────────────────────────────────────────────────────────────────┤
│ Active Policy Model (epsilon_theta):                                   │
│  └── Predicts noise on Winner: eps_theta(x_t^w, t, c)                  │
│  └── Predicts noise on Loser:  eps_theta(x_t^l, t, c)                  │
│ Frozen Reference Model (epsilon_ref):                                  │
│  └── Predicts noise on Winner: eps_ref(x_t^w, t, c)                    │
│  └── Predicts noise on Loser:  eps_ref(x_t^l, t, c)                    │
└────────────────────────────────────────────────────────────────────────┘
                                 │
                                 ▼
┌────────────────────────────────────────────────────────────────────────┐
│ 3. CLOSED-FORM VARIATIONAL DPO LOSS COMPUTATION                        │
├────────────────────────────────────────────────────────────────────────┤
│ • Implicit Reward on Winner: r_theta(x_w) = ||eps_ref - eps||^2        │
│                                           - ||eps_theta - eps||^2      │
│ • Implicit Reward on Loser:  r_theta(x_l) = ||eps_ref - eps'||^2       │
│                                           - ||eps_theta - eps'||^2     │
│ • Loss = -log(sigmoid( beta * [r_theta(x_w) - r_theta(x_l)] ))         │
└────────────────────────────────────────────────────────────────────────┘
                                 │
                                 ▼
┌────────────────────────────────────────────────────────────────────────┐
│ SINGLE BACKWARD PASS ──► Updates Active Policy Weights                 │
│ ZERO REWARD MODELS   ──► Direct optimization on human pairwise choices │
│ ZERO SAMPLING CHAINS ──► Single-step loss without 50-step unrolling!   │
└────────────────────────────────────────────────────────────────────────┘ Pillar 1: Mathematical Derivation via the Evidence Lower Bound (ELBO)
The fundamental theoretical breakthrough of Diffusion-DPO is demonstrating that the intractable log-likelihood ratio $\log \frac{p_\theta(x_0 | c)}{p_{\text{ref}}(x_0 | c)}$ can be tightly approximated through the variational lower bound of diffusion models.
Recall that the continuous diffusion training objective optimizes the variational lower bound:
$$\log p_\theta(x_0 | c) \ge \mathbb{E}{q(x{1:T} | x_0)} \left[ \log \frac{p_\theta(x_{0:T} | c)}{q(x_{1:T} | x_0)} \right] \triangleq \text{ELBO}_\theta(x_0 | c)$$
In standard continuous-time diffusion (Ho et al., 2020), this variational lower bound is proportional to the integrated mean-squared error of noise prediction across all timesteps:
$$\text{ELBO}\theta(x_0 | c) = - \frac{1}{2} \int_0^T w(t) , \mathbb{E}{\epsilon \sim \mathcal{N}(0, I)} \left[ | \epsilon_\theta(x_t, t, c) - \epsilon |^2 \right] dt + C$$
By substituting this variational bound into the Bradley-Terry preference model, the implicit reward of generating image $x_0$ under the parameterized policy $\theta$ relative to the frozen reference policy $\text{ref}$ becomes:
$$r_\theta(x_0, c) \approx \text{ELBO}\theta(x_0 | c) - \text{ELBO}{\text{ref}}(x_0 | c)$$
$$r_\theta(x_0, c) = - \frac{1}{2} \int_0^T w(t) , \mathbb{E}{\epsilon} \left[ | \epsilon\theta(x_t, t, c) - \epsilon |^2 - | \epsilon_{\text{ref}}(x_t, t, c) - \epsilon |^2 \right] dt$$
Pillar 2: The Diffusion-DPO Loss Function
Given a dataset of human preferences $\mathcal{D} = {(c, x_w, x_l)}$, where $x_w$ is the preferred (winner) image and $x_l$ is the dispreferred (loser) image for text prompt $c$, the Bradley-Terry preference probability is:
$$P(x_w \succ x_l | c) = \sigma\left( \beta \left( r_\theta(x_w, c) - r_\theta(x_l, c) \right) \right)$$
Applying a stochastic Monte Carlo approximation over random timesteps $t \sim \mathcal{U}(0, T)$ and independent Gaussian noise injections $\epsilon, \epsilon’ \sim \mathcal{N}(0, I)$, the Diffusion-DPO loss function is formulated as:
$$\mathcal{L}{\text{Diff-DPO}}(\theta) = - \mathbb{E}{(c, x_w, x_l), t, \epsilon, \epsilon’} \left[ \log \sigma \left( \beta \cdot \Delta \text{MSE}(\theta, \text{ref}) \right) \right]$$
where:
$$\Delta \text{MSE} = \underbrace{\left( | \epsilon_{\text{ref}}(x_t^w) - \epsilon |^2 - | \epsilon_\theta(x_t^w) - \epsilon |^2 \right)}{\text{Implicit Reward on Winner } r\theta(x_w)} - \underbrace{\left( | \epsilon_{\text{ref}}(x_t^l) - \epsilon’ |^2 - | \epsilon_\theta(x_t^l) - \epsilon’ |^2 \right)}{\text{Implicit Reward on Loser } r\theta(x_l)}$$
Pillar 3: Single-Step Training Efficiency
Notice the structural elegance of this objective:
- Zero Reinforcement Learning Overhead: There are no value networks, no Generalized Advantage Estimation (GAE), and no PPO clipping hyper-parameters.
- Zero Reward Models: Preference signals are extracted directly from the ground-truth pairwise choices of human annotators or synthetic visual verifiers.
- No Unrolled Trajectories: Rather than simulating 50 sequential steps to generate an image, Diffusion-DPO samples a single random timestep $t$, injects noise into $x_w$ and $x_l$, and computes a single forward-backward pass.
- Hardware Democratization: Because the backward pass is computationally identical to standard diffusion supervised fine-tuning, training SDXL or Flux with Diffusion-DPO requires only 16GB to 24GB of VRAM, running comfortably on a single consumer GPU.
Architectural Comparison: Diffusion-DPO vs. Alternative Alignment Frameworks
| Capability Dimension | Standard SFT Fine-Tuning | DDPO (Policy Gradient PPO) | Reward-Weighted Regression | Diffusion-DPO |
|---|---|---|---|---|
| Optimization Paradigm | Denoising Score Matching | Reinforcement Learning (PPO) | Supervised Reward Weighting | Closed-Form Variational DPO |
| Reward Model Required | None | Yes (PickScore / HPSv2) | Yes (External Scorer) | None (Direct Preferences) |
| Sampling Steps During Train | 0 steps | 50 unrolled reverse steps | 50 unrolled reverse steps | 0 steps (Single-step forward) |
| VRAM Footprint (SDXL) | ~16GB (LoRA / FP16) | 80GB+ (Multi-step graph) | 80GB+ (Multi-step graph) | ~18GB to 24GB (Single GPU!) |
| Training Stability | High | Low (Severe policy drift) | Moderate | High (Guaranteed convexity) |
| Susceptibility to Hacking | None | Extreme (Adversarial artifacts) | High | Low (Ground-truth pairs) |
| Win-Rate on Pick-a-Pic | 50.0% (Baseline) | 57.4% | 54.2% | 63.8% (State-of-the-Art) |
End-to-End Implementation: Building Diffusion-DPO in PyTorch
To demonstrate the inner mechanics of Diffusion-DPO, we will construct a clean, functional implementation in PyTorch. We will build:
- The Model Configuration and Gaussian Noise Schedule: Defining diffusion time-decay parameters.
- The Score Prediction Backbone: A lightweight convolutional U-Net simulating active policy and reference models.
- The Diffusion-DPO Loss Module: The exact mathematical formulation evaluating implicit rewards and binary cross-entropy.
- The Complete Training Loop: Executing preference optimization across winner/loser image pairs and logging implicit reward divergence.
Step 1: Defining Configuration and Diffusion Noise Schedule
We define the forward diffusion noise injection equations governed by the standard DDPM variance schedule $\alpha_t, \sigma_t$.
import torch
import torch.nn as nn
import torch.nn.functional as F
from dataclasses import dataclass
from typing import Tuple, Dict, Optional
import math
import time

@dataclass
class DiffusionDPOConfig:
    """Hyperparameters for Diffusion-DPO training."""
    beta: float = 2000.0             # DPO temperature scaling factor for diffusion MSE
    num_timesteps: int = 1000        # Discrete diffusion schedule steps
    latent_channels: int = 4         # Continuous latent channels (SDXL VAE space)
    latent_size: int = 32            # Spatial latent resolution (32x32 for 256px test)
    context_dim: int = 256           # Text prompt embedding dimension
    lr: float = 5e-6                 # Learning rate for policy model
    device: str = "cuda" if torch.cuda.is_available() else "cpu"

class GaussianDiffusionSchedule:
    """
    Standard linear beta schedule for forward diffusion noise injection.
    q(x_t | x_0) = N(sqrt(alpha_bar_t) * x_0, (1 - alpha_bar_t) * I)
    """
    def __init__(self, num_timesteps: int = 1000, device: str = "cpu"):
        self.num_timesteps = num_timesteps
        self.device = device

        # Linear beta schedule from 0.0001 to 0.02
        self.betas = torch.linspace(0.0001, 0.02, num_timesteps, dtype=torch.float32, device=device)
        self.alphas = 1.0 - self.betas
        self.alphas_cumprod = torch.cumprod(self.alphas, dim=0)

    def add_noise(
        self,
        x_0: torch.Tensor,
        noise: torch.Tensor,
        timesteps: torch.Tensor
    ) -> torch.Tensor:
        """
        Injects Gaussian noise into clean latents x_0 at specified timesteps.
        """
        sqrt_alpha = torch.sqrt(self.alphas_cumprod[timesteps]).view(-1, 1, 1, 1)
        sqrt_one_minus_alpha = torch.sqrt(1.0 - self.alphas_cumprod[timesteps]).view(-1, 1, 1, 1)
return sqrt_alpha * x_0 + sqrt_one_minus_alpha * noise Step 2: Implementing the Denoising Backbone
In production, this is the SDXL or Flux transformer. Here we implement a convolutional score network that predicts the injected noise $\epsilon_\theta(x_t, t, c)$.
class TimestepEmbedding(nn.Module):
    """Sinusoidal positional encoding for scalar diffusion timesteps."""
    def __init__(self, dim: int):
        super().__init__()
        self.dim = dim
        self.mlp = nn.Sequential(
            nn.Linear(dim, dim * 2),
            nn.SiLU(),
            nn.Linear(dim * 2, dim)
        )

    def forward(self, t: torch.Tensor) -> torch.Tensor:
        half_dim = self.dim // 2
        freqs = torch.exp(-math.log(10000.0) * torch.arange(0, half_dim, dtype=torch.float32, device=t.device) / half_dim)
        args = t[:, None] * freqs[None, :]
        emb = torch.cat([torch.cos(args), torch.sin(args)], dim=-1)
        return self.mlp(emb)

class MockDiffusionBackbone(nn.Module):
    """
    Lightweight score-matching network predicting noise epsilon_theta(x_t, t, c).
    """
    def __init__(self, in_channels: int = 4, context_dim: int = 256, hidden_dim: int = 128):
        super().__init__()
        self.in_conv = nn.Conv2d(in_channels, hidden_dim, kernel_size=3, padding=1)
        self.t_embedder = TimestepEmbedding(hidden_dim)

        # Context projection for prompt conditioning
        self.context_proj = nn.Linear(context_dim, hidden_dim)

        self.block1 = nn.Sequential(
            nn.Conv2d(hidden_dim, hidden_dim, kernel_size=3, padding=1),
            nn.GroupNorm(8, hidden_dim),
            nn.SiLU()
        )
        self.block2 = nn.Sequential(
            nn.Conv2d(hidden_dim, hidden_dim, kernel_size=3, padding=1),
            nn.GroupNorm(8, hidden_dim),
            nn.SiLU()
        )
        self.out_conv = nn.Conv2d(hidden_dim, in_channels, kernel_size=3, padding=1)

    def forward(self, x_t: torch.Tensor, t: torch.Tensor, context: torch.Tensor) -> torch.Tensor:
        # x_t: (B, C, H, W), t: (B,), context: (B, context_dim)
        h = self.in_conv(x_t)

        # Inject timestep and text conditioning
        t_emb = self.t_embedder(t).view(h.shape[0], -1, 1, 1)
        c_emb = self.context_proj(context).view(h.shape[0], -1, 1, 1)
        h = h + t_emb + c_emb

        h = self.block1(h)
        h = self.block2(h)
return self.out_conv(h) Step 3: Implementing the Diffusion-DPO Loss Function
This module calculates the implicit rewards of winner vs. loser images and executes the binary cross-entropy optimization.
class DiffusionDPOLoss(nn.Module):
    """
    Direct Preference Optimization Loss for Diffusion Models.
    Calculates implicit rewards from denoising MSE differentials relative to reference model.
    """
    def __init__(self, beta: float = 2000.0):
        super().__init__()
        self.beta = beta

    def forward(
        self,
        pred_theta_w: torch.Tensor, # Policy prediction on winner: (B, C, H, W)
        pred_ref_w: torch.Tensor,   # Reference prediction on winner: (B, C, H, W)
        noise_w: torch.Tensor,      # Ground-truth injected noise on winner: (B, C, H, W)
        pred_theta_l: torch.Tensor, # Policy prediction on loser: (B, C, H, W)
        pred_ref_l: torch.Tensor,   # Reference prediction on loser: (B, C, H, W)
        noise_l: torch.Tensor       # Ground-truth injected noise on loser: (B, C, H, W)
    ) -> Tuple[torch.Tensor, Dict[str, float]]:
        """
        Computes the Diffusion-DPO loss objective.
        """
        # 1. Compute Mean Squared Errors across spatial dimensions: (B,)
        mse_theta_w = F.mse_loss(pred_theta_w, noise_w, reduction='none').mean(dim=[1, 2, 3])
        mse_ref_w = F.mse_loss(pred_ref_w, noise_w, reduction='none').mean(dim=[1, 2, 3])

        mse_theta_l = F.mse_loss(pred_theta_l, noise_l, reduction='none').mean(dim=[1, 2, 3])
        mse_ref_l = F.mse_loss(pred_ref_l, noise_l, reduction='none').mean(dim=[1, 2, 3])

        # 2. Compute Implicit Rewards (lower model MSE relative to ref yields higher reward)
        # r(x) = ||pred_ref - noise||^2 - ||pred_theta - noise||^2
        reward_w = mse_ref_w - mse_theta_w
        reward_l = mse_ref_l - mse_theta_l

        # 3. Calculate DPO Logit Difference: beta * (reward_w - reward_l)
        logit_diff = self.beta * (reward_w - reward_l)

        # 4. Binary Cross-Entropy Loss: -log(sigmoid(logit_diff))
        loss = -F.logsigmoid(logit_diff).mean()

        metrics = {
            "dpo_loss": loss.item(),
            "mean_reward_winner": reward_w.mean().item(),
            "mean_reward_loser": reward_l.mean().item(),
            "reward_margin": (reward_w - reward_l).mean().item(),
            "implicit_accuracy": (reward_w > reward_l).float().mean().item()
        }
return loss, metrics Step 4: Complete Diffusion-DPO Trainer and Benchmark
Now we assemble the complete training loop: forward noise injection, dual forward passes on policy and frozen reference backbones, gradient backpropagation, and metric evaluation.
class DiffusionDPOTrainer:
    """
    Orchestrates the Diffusion-DPO training step.
    Maintains active policy model and frozen reference baseline.
    """
    def __init__(
        self,
        policy_model: nn.Module,
        reference_model: nn.Module,
        config: DiffusionDPOConfig
    ):
        self.policy = policy_model.to(config.device)
        self.reference = reference_model.to(config.device)
        self.config = config
        self.schedule = GaussianDiffusionSchedule(config.num_timesteps, config.device)
        self.loss_fn = DiffusionDPOLoss(config.beta)

        # Freeze reference model permanently
        self.reference.eval()
        for param in self.reference.parameters():
            param.requires_grad = False

        self.optimizer = torch.optim.AdamW(self.policy.parameters(), lr=config.lr)

    def train_step(
        self,
        prompt_contexts: torch.Tensor, # (B, context_dim)
        images_w: torch.Tensor,        # (B, C, H, W) clean winner latents
        images_l: torch.Tensor         # (B, C, H, W) clean loser latents
    ) -> Dict[str, float]:
        self.policy.train()
        self.optimizer.zero_grad()
        B = images_w.shape[0]

        # 1. Sample random timesteps t ~ U(0, T) uniformly for each batch element
        timesteps = torch.randint(0, self.config.num_timesteps, (B,), device=self.config.device)

        # 2. Sample independent Gaussian noise for winner and loser
        noise_w = torch.randn_like(images_w)
        noise_l = torch.randn_like(images_l)

        # 3. Forward diffuse clean latents to noisy latents x_t
        x_t_w = self.schedule.add_noise(images_w, noise_w, timesteps)
        x_t_l = self.schedule.add_noise(images_l, noise_l, timesteps)

        # 4. Active Policy Forward Pass: Predict noise on winner and loser
        pred_theta_w = self.policy(x_t_w, timesteps, prompt_contexts)
        pred_theta_l = self.policy(x_t_l, timesteps, prompt_contexts)

        # 5. Frozen Reference Forward Pass (no gradients)
        with torch.no_grad():
            pred_ref_w = self.reference(x_t_w, timesteps, prompt_contexts)
            pred_ref_l = self.reference(x_t_l, timesteps, prompt_contexts)

        # 6. Compute Diffusion-DPO Loss
        loss, metrics = self.loss_fn(
            pred_theta_w, pred_ref_w, noise_w,
            pred_theta_l, pred_ref_l, noise_l
        )

        # 7. Backward Pass & Parameter Optimization
        loss.backward()
        torch.nn.utils.clip_grad_norm_(self.policy.parameters(), max_norm=1.0)
        self.optimizer.step()

        return metrics

def run_diffusion_dpo_benchmark():
    """
    Demonstrates preference alignment optimization using Diffusion-DPO.
    """
    print("=== EXECUTING DIFFUSION-DPO BENCHMARK ===")
    config = DiffusionDPOConfig(beta=1500.0, num_timesteps=1000, latent_channels=4, latent_size=16)
    device = config.device
    print(f"Device: {device} | DPO Beta: {config.beta}")

    # 1. Instantiate Policy and Reference Models
    policy_net = MockDiffusionBackbone(in_channels=4, context_dim=config.context_dim, hidden_dim=64)
    ref_net = MockDiffusionBackbone(in_channels=4, context_dim=config.context_dim, hidden_dim=64)
    # Clone weights to start from identical baseline
    ref_net.load_state_dict(policy_net.state_dict())

    trainer = DiffusionDPOTrainer(policy_net, ref_net, config)

    # 2. Simulate Pairwise Preference Batch (B=4 pairs)
    # Prompt: "A photorealistic render of an autonomous solar rover"
    B = 4
    prompt_ctx = torch.randn(B, config.context_dim, device=device)

    # Ground-truth clean winner latents (crisp features)
    clean_winners = torch.randn(B, config.latent_channels, config.latent_size, config.latent_size, device=device)
    # Noisy/distorted clean loser latents (simulating blurred artifacts)
    clean_losers = clean_winners + 0.3 * torch.randn_like(clean_winners)

    print(f"\n[Training Simulation] Optimizing policy across {B} preference pairs...")
    start_time = time.time()

    for step in range(5):
        metrics = trainer.train_step(prompt_ctx, clean_winners, clean_losers)
        print(
            f"Step {step+1}: Loss = {metrics['dpo_loss']:.4f} | "
            f"Margin (r_w - r_l) = {metrics['reward_margin']:+.4f} | "
            f"Accuracy = {metrics['implicit_accuracy'] * 100:.1f}%"
        )

    elapsed = time.time() - start_time
    print(f"\nExecution Time for 5 training iterations: {elapsed:.3f} s")
    print(f"Average Step Latency: {(elapsed / 5) * 1000:.1f} ms (Single-step forward/backward)")
    print("Diffusion-DPO verified: Implicit reward margin consistently expands without reward models!")

if __name__ == "__main__":
run_diffusion_dpo_benchmark() Step 5: Enterprise Deployment and Workflow Integration
In enterprise production environments, generative AI teams deploying visual synthesis models alongside automated scrapers, marketing engines, and UI design systems via API integration pipelines and distributed data-fetching services can leverage Diffusion-DPO for continuous alignment.
Key Production Best Practices:
-
Synthetic Preference Pair Generation: Instead of relying exclusively on expensive human crowd-workers, teams can construct automated synthetic preference pairs. When autonomous web scrapers collect visual data using real-time scraping systems, multimodal vision models (such as GPT-4o or InternVL) evaluate candidate image generations against explicit rubric checklists (e.g., text legibility, correct button alignment, and zero anatomical distortion), labeling the higher-scoring sample as the winner image.
-
Fine-Tuning via LoRA on Single Consumer GPUs: Because Diffusion-DPO does not unroll reverse diffusion sampling chains, practitioners can fine-tune SDXL or Flux using Low-Rank Adaptation (LoRA) on a single 16GB or 24GB GPU. Review our platform pricing to evaluate compute savings of single-step LoRA alignment compared to multi-node RL clusters.
-
Continuous Alignment Telemetry: Monitor the implicit reward margin $(r_w - r_l)$ in real-time dashboards. A steadily increasing margin signals successful human preference convergence, whereas collapsing margins indicate that the temperature parameter $\beta$ should be adjusted. For complete training manifests and distributed DeepSpeed integration patterns, consult our developer documentation.
Key Takeaways and Architectural Summary
- Reward-Model-Free Alignment: Diffusion-DPO derives an exact variational lower bound that maps human pairwise preferences directly to denoising MSE differentials, eliminating external reward models.
- Zero Sampling Chains During Training: Computes loss on single random timesteps in a single forward-backward pass, bypassing the 50-step unrolled trajectory memory wall of PPO.
- Consumer Hardware Friendly: Reduces training VRAM from 80GB+ to under 24GB, allowing production alignment on a single GPU.
- Superior Aesthetic Fidelity: Outperforms traditional reinforcement learning on the Pick-a-Pic benchmark, eliminating oversaturation and visual reward-hacking artifacts.