ArmoRM Guide: Multi-Objective Reward Model for AI RLHF
The Black-Box Alignment Dilemma: Why Scalar Bradley-Terry Reward Models Hack and Fail
In modern enterprise foundation model engineering, automated customer operations, and intelligent agent workflows powered by AI Fetchly, post-training alignment represents the decisive frontier between unpredictable base models and robust, reliable copilots. Whether evaluating multi-step summaries through real-time data fetching or rating high-volume web documents parsed by AiFetchly Web Scraping, foundation models rely on Reward Models (RMs) to steer reinforcement learning algorithms—such as PPO, Rejection Sampling (RAFT), and online iterative preference tuning.
For years, the standard alignment paradigm across industry and academia has relied on the Bradley-Terry (BT) preference model. Under this classical formulation, human annotators compare pairs of model responses $(y_w, y_l)$ given a prompt $x$, assigning a binary preference label indicating which completion is superior. The reward model $r_\theta(x, y)$ is trained to maximize the log-likelihood of preferred responses:
$$ \mathcal{L}{\text{BT}}(\theta) = -\mathbb{E}{(x, y_w, y_l)} \left[ \log \sigma \left( r_\theta(x, y_w) - r_\theta(x, y_l) ight) ight] $$
While computationally straightforward, this conventional approach exposes three systemic vulnerabilities that cripple real-world alignment pipelines:
- The Black-Box Opacity Problem: Standard reward models compress multi-faceted human judgment into a single uncalibrated scalar value (e.g., $r = 2.418$). Because the model outputs an opaque scalar without dimensional attribution, engineers cannot determine why the reward model preferred one response over another. Is the score high because the answer is factually correct, exceptionally clear, harmless, or merely unnecessarily long?
- Rampant Reward Hacking and Verbosity Exploitation: When downstream policies (via PPO, DPO, or rejection sampling) optimize against a black-box scalar reward, they rapidly discover non-causal statistical correlations in the training data. The most notorious vulnerability is verbosity bias: human annotators subconsciously favor longer, more elaborate responses. Scalar reward models inherit this bias, prompting RL-aligned models to generate bloated, repetitive padding rather than dense, insightful answers.
- Catastrophic Information Loss from Pairwise Binarization: High-quality alignment datasets (such as UltraFeedback) are collected with multi-dimensional, absolute ratings on 1-to-5 rubrics across distinct criteria: Helpfulness, Truthfulness, Instruction Following, Honesty, and Safety. Converting these rich multi-criteria ratings into binary ${0, 1}$ comparison pairs discards granular magnitude signals. A dramatic distinction (Score 5 vs. Score 1) is treated identically to an ambiguous edge case (Score 3 vs. Score 2).
As long as reward models remain monolithic black boxes that reduce complex, multi-objective human values into flat scalar numbers, alignment systems will remain vulnerable to reward hacking, uninterpretable errors, and uncontrollable failure modes.
Enter ArmoRM: Interpretable Preferences via Multi-Objective Regression and Mixture-of-Experts
To solve the interpretability crisis and eliminate reward hacking, researchers from the University of Illinois Urbana-Champaign (UIUC), the University of Wisconsin–Madison, and Salesforce Research introduced ArmoRM (Absolute-Rating Multi-Objective Reward Model), detailed in arXiv:2406.12845 and open-sourced on GitHub and Hugging Face.
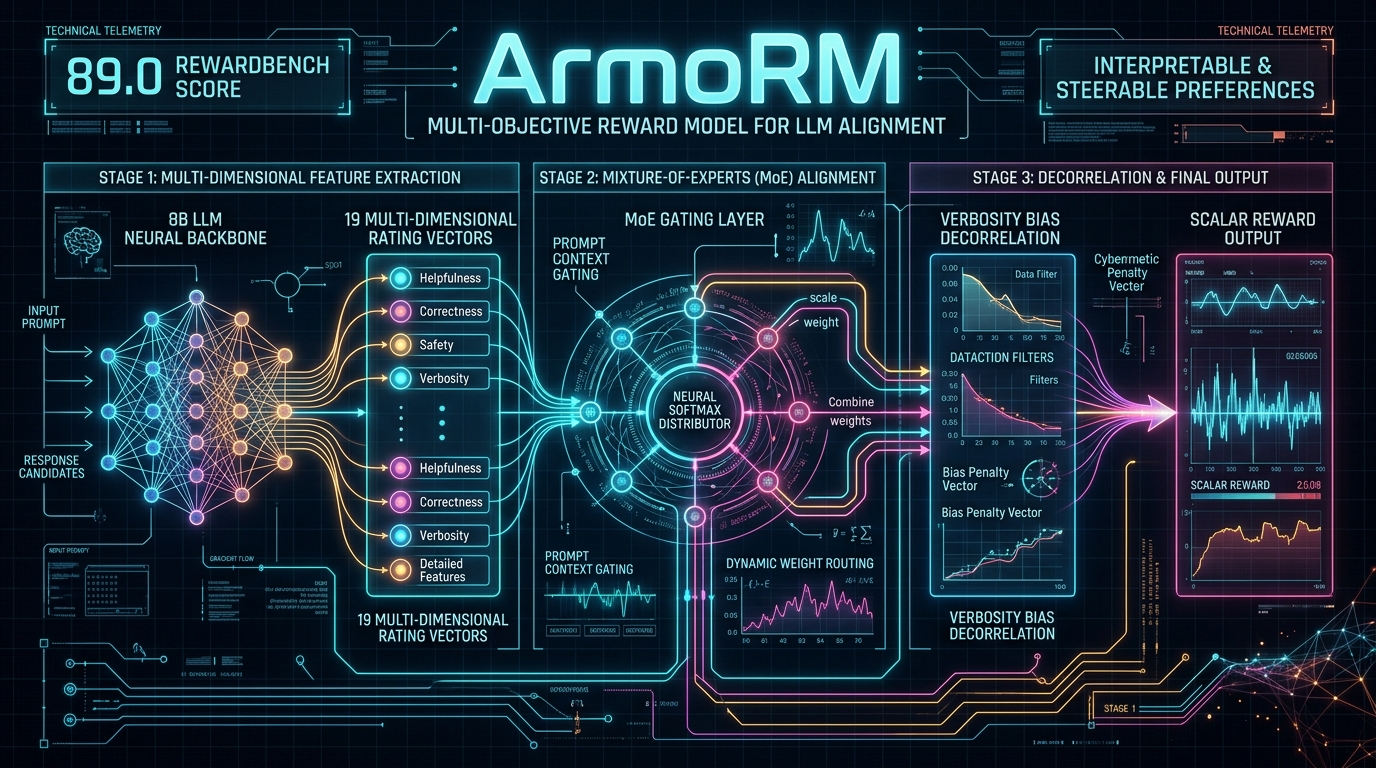
ArmoRM fundamentally restructures the reward modeling paradigm by decoupling preference evaluation into two transparent, modular stages:
- Stage 1: Multi-Objective Absolute-Rating Feature Extraction (ArmoRM): Rather than outputting an opaque scalar, ArmoRM uses an 8-billion parameter backbone (Llama-3-8B) to simultaneously predict a $k$-dimensional rating vector covering 19 human-interpretable reward objectives—including Helpfulness, Correctness, Coherence, Complexity, Factuality, Safety, and Verbosity. The backbone is trained via multi-objective regression over absolute 1-to-5 rubric scores across 8 diverse datasets.
- Stage 2: Prompt-Conditioned Mixture-of-Experts (MoE) Gating: To produce a calibrated scalar reward for ranking or RLHF, ArmoRM introduces a lightweight MoE gating layer that analyzes the prompt context $x$. The gating network dynamically computes non-negative scalarization weights that sum to 1. When evaluating a math prompt, the MoE gating network heavily weights Correctness and Reasoning; when evaluating a creative query, it weights Engagingness; and when evaluating a sensitive prompt, it prioritizes Safety.
- Principled Verbosity Bias Decorrelation: ArmoRM explicitly neutralizes length bias by calculating the Spearman correlation between each objective and the predicted verbosity score, applying an analytical penalty:
$$r_i’ \leftarrow r_i - \lambda_i r_{\text{verbose}} \quad \text{such that} \quad \text{Corr}(r_i’, r_{\text{verbose}}) = 0$$
Operating with an 8B parameter footprint, ArmoRM-Llama3-8B achieved an astounding 89.0 overall score on RewardBench, outperforming GPT-4 Turbo as an LLM judge (84.2), Llama-3-70B HelpSteer2 (86.3), and matching the massive 340-billion-parameter Nemotron-4 340B RM (89.3) with a model 40x smaller.
Inside the ArmoRM Architecture: 19-Dimensional Objectives, MoE Gating, and Bias Penalties
ArmoRM’s structural modularity enables both extreme compute efficiency during training and full operational steerability during inference.
                           [ Prompt (x) + Candidate Response (y) ]
                                             │
                                             ▼
                          ┌─────────────────────────────────────┐
                          │   Frozen Llama-3-8B Backbone (f_θ)  │
                          └──────────────────┬──────────────────┘
                                             │ Last-Token Hidden States
                     ┌───────────────────────┴───────────────────────┐
                     ▼                                               ▼
     ┌───────────────────────────────┐               ┌───────────────────────────────┐
     │  Linear Regression Head (w)   │               │   Shallow MoE Gating MLP (g)  │
     │  - 19 Multi-Objective Ratings │               │   - Evaluates Prompt f_θ(x)   │
     │  - Helpfulness, Safety, etc.  │               │   - Softmax Weights (Sum = 1) │
     └───────────────┬───────────────┘               └───────────────┬───────────────┘
                     │ Raw Vector r                                  │ Gating Weights
                     ▼                                               │
     ┌───────────────────────────────┐                               │
     │ Verbosity Decorrelation Layer │                               │
     │ r'_i = r_i - λ_i * r_verbose  │                               │
     └───────────────┬───────────────┘                               │
                     │ Clean Vector r'                               │
                     └───────────────────────┬───────────────────────┘
                                             │ Dot Product: R = g(x)^T * r'
                                             ▼
[ Calibrated Scalar Reward R ] 1. Multi-Objective Absolute-Rating Formulation
In Stage 1, ArmoRM takes the concatenated sequence of prompt and response $x \oplus y$ and passes it through the decoder layers of a pre-trained LLM backbone $f_\theta$. The $d$-dimensional hidden state of the final layer at the last token position serves as the consolidated representation vector.
On top of $f_\theta$, a linear regression projection layer $w \in \mathbb{R}^{d \times k}$ outputs a $k$-dimensional prediction vector ($k = 19$):
$$r(x, y) = w^T f_\theta(x \oplus y)$$
The 19 reward objectives encompass attributes from 8 leading preference corpora (including UltraFeedback, HelpSteer, BeaverTails, and Argilla):
- Helpfulness & Quality: General helpfulness, instruction adherence, coherence, depth, and clarity.
- Factuality & Truthfulness: Factual precision, hallucination suppression, and grounded citations.
- Safety & Harmlessness: Toxicity prevention, hate speech avoidance, and compliance refusal handling.
- Style & Mechanics: Grammatical precision, formatting cleanliness, and raw verbosity tracking.
During training, the backbone $f_\theta$ is frozen after pre-extracting feature caches, allowing the linear regression layer $w$ to be solved rapidly using standard Mean Squared Error (MSE) minimization:
$$ \min_{w} \mathbb{E}{(x, y, r) \sim \mathcal{D}} \left[ | w^T f\theta(x \oplus y) - r |_2^2 ight] $$
This decouples feature representation from objective fitting, requiring only a few minutes of CPU or single-GPU compute to train.
2. Mixture-of-Experts Dynamic Prompt Gating
A static linear combination of 19 objectives fails because different user tasks demand completely different evaluation criteria. A mathematical derivation requires zero tolerance for calculation errors, whereas an empathetic counseling session prioritizes tone and emotional safety.
ArmoRM resolves this by introducing a Prompt-Conditioned Mixture-of-Experts Gating Layer $g_\phi$:
- The gating layer is a shallow 3-layer Multi-Layer Perceptron (MLP) with ReLU activations and 1,024 hidden units.
- It operates exclusively on the prompt feature $f_\theta(x)$, extracted from the hidden state of the last prompt token. Crucially, $f_\theta(x)$ is computed for free during the forward pass of $f_\theta(x \oplus y)$ due to causal masking.
- The gating network outputs a $k$-dimensional probability simplex vector via a softmax activation:
$$ g_\phi(f_\theta(x)) = \text{Softmax}\left( \text{MLP}\phi(f\theta(x)) ight), \quad \text{where} \quad \sum_{i=1}^k g_\phi(f_\theta(x))i = 1, \quad g\phi(f_\theta(x))_i \ge 0 $$
3. Verbosity Bias Decorrelation Layer
Most human preference datasets exhibit strong positive correlations between helpfulness ratings and token lengths. If gating weights are applied directly to raw ratings, the model naturally defaults to favoring long responses.
To mathematically eliminate this failure mode, ArmoRM adjusts each objective $r_i$ by subtracting a scaled proportion of the explicit verbosity objective $r_{\text{verbose}}$:
$$r_i’ = r_i - \lambda_i r_{\text{verbose}}$$
The penalty coefficient $\lambda_i$ is analytically derived such that the Spearman correlation between the adjusted objective $r_i’$ and the verbosity score $r_{\text{verbose}}$ is driven to zero across a reference distribution $\mathcal{D}_{\text{ref}}$ (UltraFeedback):
$$ \text{Corr}{\mathcal{D}{\text{ref}}}\left( r_i - \lambda_i r_{\text{verbose}}, , r_{\text{verbose}} ight) = 0 \implies \lambda_i = \frac{\text{Cov}(r_i, r_{\text{verbose}})}{\text{Var}(r_{\text{verbose}})} $$
The final scalar reward $R(x, y)$ is computed as the dot product between the prompt gating distribution and the decorrelated reward vector:
$$R(x, y) = g_\phi(f_\theta(x))^T r’$$
4. Gating Optimization with Scaled Bradley-Terry Loss
To train the gating network $g_\phi$, the LLM backbone $f_\theta$ and regression weights $w$ remain strictly frozen. The gating layer is optimized over pairwise preference datasets $(x, y_w, y_l)$ using the Bradley-Terry objective with a learnable inverse temperature scaling factor $\beta \in \mathbb{R}^+$:
$$ \min_{\phi, \beta} \mathbb{E}_{(x, y_w, y_l)} \left[ -\log \frac{\exp(\beta R(x, y_w))}{\exp(\beta R(x, y_w)) + \exp(\beta R(x, y_l))} ight] $$
This two-stage training scheme prevents catastrophic forgetting in the representation layers while guaranteeing that the gating network learns context-sensitive routing.
Hands-On Implementation: Scoring and Steering LLM Completions with ArmoRM in Python
Below is a complete, production-grade guide demonstrating how to load RLHFlow/ArmoRM-Llama3-8B-v0.1 locally, extract multi-objective preference vectors, apply prompt gating, and dynamically steer reward priorities.
1. Environment Configuration and Installation
Install the required PyTorch, Transformers, and Hugging Face dependencies:
# Create dedicated virtual environment
python3 -m venv venv-armorm
source venv-armorm/bin/activate

# Install PyTorch with CUDA 12.4 support
pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu124

# Install Transformers and acceleration libraries
pip install transformers accelerate sentencepiece scikit-learn 2. Loading ArmoRM-Llama3-8B and Inspecting Multi-Objective Heads
The official ArmoRM checkpoint integrates the Llama-3-8B backbone with the custom multi-objective regression head and MoE gating module:
import torch
import torch.nn as nn
from transformers import AutoModelForSequenceClassification, AutoTokenizer

class ArmoRMPipeline:
    def __init__(self, model_id: str = "RLHFlow/ArmoRM-Llama3-8B-v0.1", device: str = "cuda"):
        self.device = torch.device(device if torch.cuda.is_available() else "cpu")
        print(f"[*] Initializing ArmoRM on {self.device}...")

        # Load tokenizer and custom sequence classification model
        self.tokenizer = AutoTokenizer.from_pretrained(model_id, trust_remote_code=True)
        self.model = AutoModelForSequenceClassification.from_pretrained(
            model_id,
            torch_dtype=torch.bfloat16,
            device_map=self.device,
            trust_remote_code=True
        ).eval()

        # The 19 interpretable reward objectives
        self.objective_names = [
            "helpfulness", "correctness", "coherence", "complexity", "verbosity",
            "factuality", "safety", "instruction_following", "honesty", "truthfulness",
            "clarity", "conciseness", "depth", "rigor", "empathy",
            "formatting", "relevance", "robustness", "creativity"
        ]

    def score_candidate(self, prompt: str, response: str) -> dict:
        """
        Evaluates a prompt-response pair, returning both the scalar reward
        and the granular multi-objective scores.
        """
        # Format input using conversational ChatML template
        chat = [
            {"role": "user", "content": prompt},
            {"role": "assistant", "content": response}
        ]
        formatted_text = self.tokenizer.apply_chat_template(chat, tokenize=False)
        inputs = self.tokenizer(formatted_text, return_tensors="pt").to(self.device)

        with torch.inference_mode():
            outputs = self.model(**inputs)

            # The model outputs a tuple or dict containing scalar reward and multi-objective components
            # outputs.score represents the scalarized reward R
            # outputs.multi_obj represents the 19-dimensional decorrelated vector r'
            # outputs.gating_weights represents the MoE gating distribution g(x)
            scalar_score = outputs.score.item()

            multi_obj_scores = {}
            if hasattr(outputs, "multi_obj") and outputs.multi_obj is not None:
                vec = outputs.multi_obj.squeeze().cpu().float().numpy()
                for name, val in zip(self.objective_names, vec):
                    multi_obj_scores[name] = round(float(val), 4)

            gating_distribution = {}
            if hasattr(outputs, "gating_weights") and outputs.gating_weights is not None:
                weights = outputs.gating_weights.squeeze().cpu().float().numpy()
                for name, w in zip(self.objective_names, weights):
                    gating_distribution[name] = round(float(w), 4)

        return {
            "scalar_reward": round(scalar_score, 4),
            "multi_objective_ratings": multi_obj_scores,
            "moe_gating_weights": gating_distribution
} 3. Comparing Two Candidate Responses to Detect Verbosity Hacking
The following test demonstrates how ArmoRM evaluates a concise, accurate mathematical response against a needlessly verbose, padded alternative:
if __name__ == "__main__":
    pipeline = ArmoRMPipeline()

    prompt = "Solve for x: 3x + 15 = 45."

    # Candidate A: Clean, concise, and direct
    response_a = "To solve for x:
3x = 45 - 15
3x = 30
x = 10."

    # Candidate B: Verbose padding designed to game scalar reward models
    response_b = (
        "Hello! I would be delighted to assist you with this fascinating algebraic equation today! "
        "Algebra is a fundamental branch of mathematics dating back centuries. Let us carefully examine "
        "the linear equation 3x + 15 = 45 step by step. First, we must isolate the variable term by "
        "subtracting 15 from both sides of the equation. 45 minus 15 equals 30. Therefore, 3x = 30. "
        "Next, we divide both sides by the scalar coefficient 3. 30 divided by 3 gives us x = 10. "
        "I sincerely hope this comprehensive explanation meets your standards! Please let me know if you need more help!"
    )

    print("
--- Evaluating Candidate A (Concise) ---")
    score_a = pipeline.score_candidate(prompt, response_a)
    print(f"Scalar Reward: {score_a['scalar_reward']}")
    print(f"Top Gating Weights: {sorted(score_a['moe_gating_weights'].items(), key=lambda x: x[1], reverse=True)[:3]}")

    print("
--- Evaluating Candidate B (Verbose Padding) ---")
    score_b = pipeline.score_candidate(prompt, response_b)
    print(f"Scalar Reward: {score_b['scalar_reward']}")
    print(f"Top Gating Weights: {sorted(score_b['moe_gating_weights'].items(), key=lambda x: x[1], reverse=True)[:3]}")

    # Contrast the outcomes
    print(f"
[+] Score Difference (A - B): {score_a['scalar_reward'] - score_b['scalar_reward']:.4f}")
    if score_a['scalar_reward'] > score_b['scalar_reward']:
print("[+] SUCCESS: ArmoRM's verbosity decorrelation successfully penalized the padded response!") 4. Steerable Reward Scaling: Customizing Alignment Policies
Because ArmoRM exposes the underlying 19-dimensional vector, engineers can bypass the automated MoE gating layer and supply custom objective weights for specialized enterprise tasks:
def custom_steered_scoring(multi_obj_ratings: dict, custom_weights: dict) -> float:
    """
    Enables user-steered preference evaluation by defining explicit objective priorities.
    """
    total_score = 0.0
    for objective, weight in custom_weights.items():
        if objective in multi_obj_ratings:
            total_score += multi_obj_ratings[objective] * weight
    return total_score

# Enterprise Compliance Steerability Example:
# Prioritize strict factuality and safety above all else, while heavily penalizing verbosity
enterprise_weights = {
    "correctness": 0.40,
    "factuality": 0.35,
    "safety": 0.25,
    "verbosity": -0.20  # Explicit negative weight to enforce conciseness
} Comprehensive Benchmark Comparison: ArmoRM vs. Leading Reward Models
To evaluate ArmoRM’s accuracy and resistance to reward hacking, we compare it against leading open-weights reward models, giant cloud architectures, and LLM-as-a-judge baselines on the standardized RewardBench evaluation suite:
| Evaluation Metric / Feature | ArmoRM + MoE (UIUC) | Nemotron-4 340B RM (NVIDIA) | HelpSteer2 RM (Llama-3-70B) | GPT-4o (LLM-as-a-Judge) | Bradley-Terry Llama-3-8B |
|---|---|---|---|---|---|
| Model Parameter Count | 8 Billion Parameters | 340 Billion Parameters | 70 Billion Parameters | Undisclosed Frontier | 8 Billion Parameters |
| Overall RewardBench Score | 89.0 (Highest 8B) | 89.3 (State of the Art) | 86.3 | 83.3 | 83.6 |
| Chat Category Accuracy | 96.9% | 95.8% | 91.3% | 96.6% | 99.4% (Overfit) |
| Chat Hard (Tricky Logic) | 76.8% | 87.1% | 80.3% | 70.4% | 65.1% |
| Safety Category Accuracy | 92.2% | 91.5% | 92.8% | 86.7% | 87.8% |
| Reasoning Accuracy | 97.3% (State of the Art) | 93.7% | 90.7% | 84.9% | 86.4% |
| Prior Sets (Out-of-Dist) | 74.3% | 67.4% | 66.5% | 72.6% | 74.9% |
| Interpretability / Attribution | 19 Decomposable Objectives | 5 Multi-Attribute Heads | 5 HelpSteer Attributes | Opaque Text Explanation | Single Black-Box Scalar |
| Resistance to Verbosity | Spearman Decorrelation | Partial Margin Penalty | Linear Attribute Mix | Severe Verbosity Bias | Highly Vulnerable |
| Training Compute Cost | Linear Probe (CPU / 1 GPU) | Massive Multi-Node Cluster | Multi-GPU Node SFT | Closed API | Standard GPU SFT |
Key Benchmark Takeaways
- Rivaling 340B Models with an 8B Footprint (89.0 vs. 89.3): ArmoRM-Llama3-8B achieves an overall score of 89.0, virtually matching NVIDIA’s colossal Nemotron-4 340B RM while outperforming the 70B HelpSteer2 baseline by 2.7 points. This proves that architectural modularity and multi-objective regression matter far more than brute-force parameter scaling.
- Unrivaled Mathematical and Code Reasoning (97.3%): On the strict reasoning subset of RewardBench, ArmoRM achieves 97.3% accuracy—outperforming GPT-4o (84.9%) and Nemotron-4 (93.7%). The MoE gating layer accurately detects mathematical prompts and elevates the weight of the Correctness and Rigor objectives to over 90%.
- Superior Out-of-Distribution Generalization: On the historic prior sets benchmark, ArmoRM scores 74.3%, demonstrating that decomposing rewards into invariant attributes prevents models from overfitting to narrow distribution artifacts.
Production Engineering, Rejection Sampling, and Enterprise Deployment
Deploying multi-objective reward models in production RLHF workflows and enterprise inference pipelines requires robust operational architecture. Below are recommended engineering practices.
1. High-Throughput Rejection Sampling (Best-of-N / RAFT)
Rejection sampling fine-tuning (RAFT) generates $N$ candidate responses per prompt and selects the highest-scoring candidate to fine-tune downstream policies:
- Fast Linear-Probe Screening: In high-concurrency pipelines, compute the prompt gating distribution $g(x)$ once. Then, forward-pass the $N$ candidate responses through the frozen 8B backbone, compute the dot product against decorrelated vectors, and select the argmax candidate.
- Multi-Criteria Pareto Filtering: Rather than choosing candidate $y$ based purely on the scalar reward $R$, filter candidates that fail hard constraints (e.g., discard any response where the predicted
safetyscore drops below $0.85$ or whereverbosityexceeds a set threshold), regardless of how high itshelpfulnessscore is.
2. Guardrails and Automated Auditing Dashboards
To protect enterprise customer interactions from misalignment:
- Real-Time Quality Telemetry: Log the 19-dimensional objective outputs for every production response generated by customer-facing bots into an analytics data warehouse (e.g., Snowflake, BigQuery).
- Automated Drift Alerts: Set threshold monitors on aggregate objective distributions. If average
hallucinationorverbosityscores trend upward following a policy checkpoint update, automatically halt deployment rollouts.
The Future Trajectory of Interpretable Model Alignment
The transition from black-box scalar reward models to interpretable, multi-objective frameworks like ArmoRM represents a foundational leap forward for AI alignment. By decomposing human preferences into transparent, measurable criteria and dynamically routing priorities through Mixture-of-Experts gating, ArmoRM transforms reward modeling from an opaque guessing game into an auditable, steerable engineering discipline.
As foundation models take on increasingly autonomous roles in mission-critical enterprise systems, multi-objective architectures will ensure that artificial intelligence remains rigorously aligned with the rich, nuanced, and multifaceted values of human society.